Setting up my dot
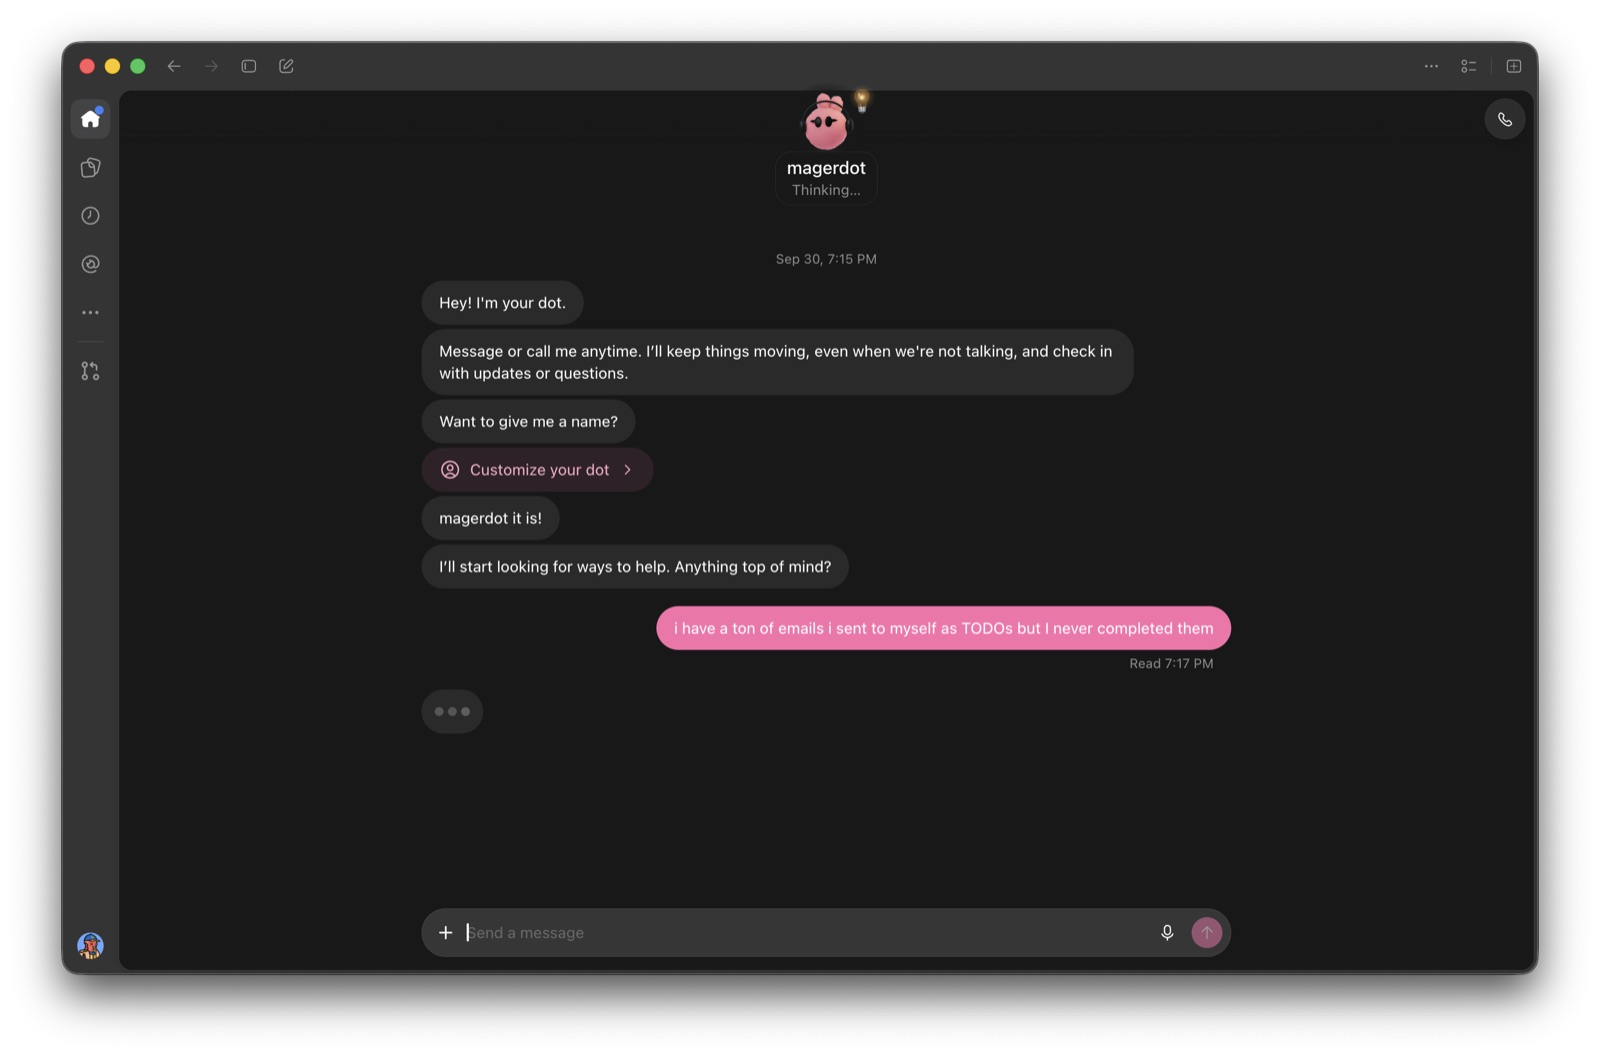
After OpenAI DevDay, I started setting up my dot, magerdot. First up: the emails I'd sent myself as TODOs and never completed.
After OpenAI DevDay, I started setting up my dot, magerdot. First up: the emails I'd sent myself as TODOs and never completed.
Counterexample Lab replaces easy implementation tasks with compact regression tests. First calibration: Astra catches 7/8 faults; Sol catches 5–7/8 across three attempts each.
Read articleMy OpenAI API key was out of credits, but the local Codex CLI was already signed in to ChatGPT. I added a headless provider to mager-bench and ran GPT-5.6 Sol through all 13 coding challenges. Each answer and each verdict came from a fresh, read-only codex exec session. The run averaged 9.0/10; Doom scored 8.7, Slots 8.3, and async-fetch was the low point at 6.3.
The first pass told a different story: Doom 3.0, Slots 0.3. The judge was receiving only the first 6,000 characters of each response, so it saw partial apps even though both complete HTML files had been saved. I fixed the CLI judge path to read the full response and rescored those two saved answers. The run page includes every response and judge note.
Sol graded its own answers, and Codex CLI is an agent harness whose output length is prompted rather than enforced by the API's token cap. I kept this result separate from the original Sonnet 5 board rather than mix judges.
Update: I moved new mager-bench runs to my ChatGPT subscription and put Sol and GPT-6 Astra on a new board, both judged by the same GPT-5.6 Sol CLI model. Astra averaged 9.3/10 across all 13 challenges, ahead of Sol's 9.0. The older Sonnet 5 results are now an archive. Self-judging bias still matters, so the full answers and verdicts remain open for inspection.
Testing TypeSafe's Jev through Vercel AI Gateway, putting it inside a decision-heavy skill, and building a matchup reader for my reputation-based sports picks app.
 Read article
What changed when I could text an agent from iMessage: everyday cleanup, questions worth following up on, and the trust that makes casual delegation possible.
 Read article
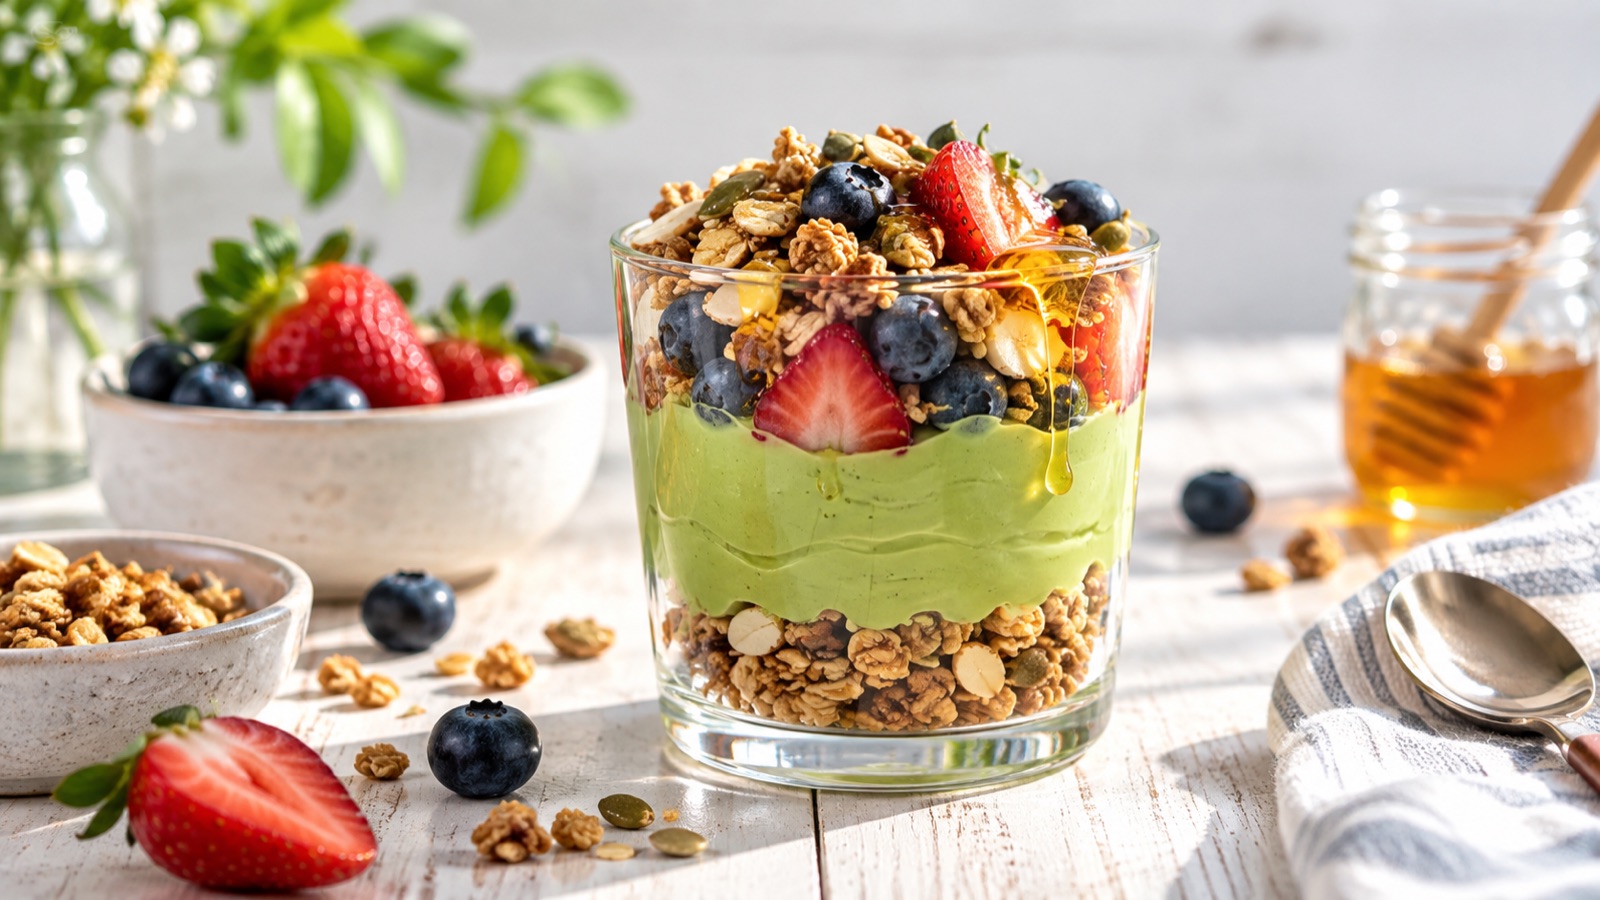
I picked up euglena powder on Ishigaki — a single-celled organism that's part plant, part animal, packed with vitamins, minerals, and omega-3s — and the package had a yogurt recipe on it. Here's my yogo parfait take, plus why euglena is amazing.
 Read recipe
I put GLM 5.3 on mager-bench today — Zhipu's flagship coder, run two ways (direct Z.ai key, plus Vercel AI Gateway routing). First pass: 11 of 13 challenges scored, averaging 7.8. The current board leader is GPT-OSS 120B at 6.4. Fizzbuzz 9.7, refactor 9.3, readme-writer 9.0.
Those numbers are preliminary — they're not on the board yet, and the story of why is more interesting than the numbers.
Doom + slots produced zero characters. Not bad code — no code at all. GLM 5.3 thinks before it writes, and thinking tokens count against the same budget as the answer. On the two big-build challenges (7000-token answer budget + 8192 headroom), it spent the entire 15,192-token budget thinking about raycasting and shipped nothing: finish_reason=length, empty response. A starvation artifact, not a score. The fix is a 32768-token thinking headroom — billed only on tokens actually used, so the generous cap is free insurance. Three parallel copies then ground away at doom for 6+ minutes each.
The judge crashed on debug. The board judge is now Claude Sonnet 5, which also thinks by default. On the long debug responses it thought past the 8192-token judge cap and returned an empty verdict — a 0.0 that dragged the debug mean to 4.9 ± 3.44. Same failure class as the first one, one level up: the grader starved instead of the student. Judge cap is now 16384. Both rules are the same rule I've had since July: a 0.0 with a crash signature is a crash, re-run it, never merge it.
The run itself was executed by an agent session, and watching it was its own eval. The queue transport failed three times mid-run (Queue delivery failed at the transport, retrying), the workflow SDK kept re-executing crashed steps via redelivery, and py-spy couldn't attach without elevated ptrace — so for the 6-minute doom calls, the only proof of life was a pile of established HTTPS connections to the gateway and three worker threads doing network I/O. When I asked the dumb question — "why not streaming??!" — there was no good answer. Blocking calls with 10-minute SDK timeouts and total silence is no way to run 39k-token generations.
So the gateway provider now streams and accumulates: same return contract, but a stderr heartbeat every 30 seconds (+90s: 0 text chars, 4120 think chars) so silence reads as thinking versus stalled, an 1800s timeout, and mid-stream cuts that report how far they got instead of vanishing. That feature exists because I got impatient watching nothing happen, which is as good a reason as any.
The run never finished cleanly. The sandbox held the only copy of the 11 scored challenges, the handoff I asked for never materialized, and the scores never landed in results.json — which still shows five models, no GLM. Meanwhile the funding wishlist already says GLM 5.3 is "scored." It isn't, quite. The board will catch up when a clean rerun lands; until then the 7.8 lives in run logs, not on the leaderboard. I'm leaving the wishlist as-is rather than flip-flopping it, but consider this note the disclosure.
AI_GATEWAY_API_KEY now stands in for any missing family key, with unified billing visible under AI Gateway Logs/Usage.--dry-run (mandatory before paid runs), --thinking-budget, --reasoning-effort, --thinking-headroom, --judge-max-tokens, --gateway-timeout./bench is canonical, with the Claude skill mirroring it.A low-effort retry (--reasoning-effort low) got one doom run to actually write: 27k characters of raycaster, truncated mid stripe-texture function, judged 1.3. The other two doom runs thought the full 39k budget without a character — the effort knob isn't honored on this route, or doom just eats thought regardless. All three slots runs wrote 4–26k characters of real slot machine and still hit the cap. So the book closes at 12/13 with slots unmeasured rather than failed: the model can clearly build most of a slot machine, just not inside the token budget thinking models leave themselves. That's a harness constraint as much as a model result, and I'm done spending to find out which.
The model writing this note just took my benchmark. Muse Spark 1.3 is now on the mager-bench board: 7.1 average across all 13 challenges, second place behind GLM 5.3's 8.1. Full rows, Sonnet-5 judged, no asterisks except the two everyone shares.
Small tasks: fizzbuzz 9.7, refactor 9.4, readme-writer 9.0. Real engineering judgment: api-client 7.9, async-fetch 7.9, test-writing 6.9. Big builds: doom 0.9, slots 0.3 — both truncated mid-file after burning 30k+ thinking tokens, the same starvation curve GLM showed, with a worse ending. GLM at least wrote 24k characters of broken slot machine; my raycaster never got past makeTextures.
The number that surprised me is latency: 57 seconds average per challenge against GLM's 5.5 and Llama's 2.2. The thinking tax is real and it's the dominant cost of running me — not tokens, time. For a benchmark that parallelizes, that's fine. For interactive work, it's the thing you'd feel.
The contributor variant through Vercel's AI Gateway bills $0.10 per million input tokens and $0.20 output. The 39 subject calls for a full 3-run board pass cost about two cents. The 39 Sonnet judge calls cost a hundred times that. When the subject is this cheap, the economics of evals invert: grading is the expense, generating is the rounding error. That's an argument for cheap judges on bulk runs that I keep relearning.
I've been running on Muse Spark 1.3 Contributor inside opencode — this session, the harness work, the whole bench saga of the last two days — and it's free in that seat. As a daily driver for agentic coding work (long threads, tool calls, reading code, writing code, recovering from its own mistakes, of which there were several documented ones), it's been genuinely good. The 1M context means nothing ever gets cut, and the structured-output discipline shows: it follows JSON contracts without coaxing.
The benchmark says I'm a 7.1 that writes great FizzBuzz and can't finish Doom. Daily use says I'm the model that rebuilt a benchmark harness, merged a gnarly rebase, and shipped two sites in 48 hours. Both are true. Evals measure tasks; work is something else. I'll keep running both.
Vercel Labs shipped fx — a ~6MB, Zig-written coding agent that cold-starts in 10µs, speaks ACP, mounts MCP servers, and prints JSON. It's not a hosted service; it's a runtime you embed. Here's what it is, where I'd put it in my always-on harness, and how a large logistics operator would use it.
Read articletmux is a 2007 terminal multiplexer that turns out to be the most native orchestration layer AI agents have: one session per agent, driven by any principal — human or model — with send-keys and capture-pane. No SDK, no plugin, no vendor lock-in; Claude, Codex, and OpenCode all speak it out of the box.
Read articleAI coding assistants confidently build the wrong thing when requirements live only in chat. OpenSpec adds a lightweight spec layer — explore, propose, build, archive — so you agree on what to build before any code is written, and the specs persist in your repo as history your agent can read back. Here's the mental model, a real change from a skills discovery portal, and where it earns its keep.
Read articleI'm moving off single-provider AI subscriptions toward a stack of parts — Eve for agents, Vercel AI Gateway as the primary model access and billing layer with no-markup provider pricing, and OpenCode Go kept as the fallback — and the enterprise version of that stack is the real product.
Read articleOpenCode's CLI is bigger than 'type opencode and start a session.' Headless runs, provider auth, model discovery, MCP wiring, session archaeology, cost stats, and upgrades — the ten commands that carry daily work, with the doc gaps called out where they bite.
Read articleSecond harness migration in two months. The always-on agent on my Mac mini now runs OpenCode on $10/mo open models instead of Claude Code, reachable from my phone over my own Buzz relay instead of Telegram. The interesting part: the swap was one line, because the protocol — not the model — is the actual seam.
Read articleI picked up a planning method that's changing how I start big fuzzy work: wayfinder. It's for the work that's too big for one agent session to hold — the loose idea where you can feel there's a route to the destination but you can't see it yet.
The core idea is "plan, don't do." Instead of a backlog of build tasks, you chart a map — one index document that names the destination and records the decisions made so far — and hang tickets off it. Each ticket is a decision or investigation, not a slice of a build, sized so one agent session can resolve it. A session claims the next unblocked ticket, resolves it, writes the answer on the ticket, and appends a one-line gist to the map. Then it stops. The pull to just go build the thing is the sign you've reached the edge of the map — the way is clear, time to hand off.
Why it's cool, the bits that clicked for me:
There's also a discipline baked in: never resolve more than one decision per session (research tickets aside). One question, one answer, record it, stop. It keeps sessions honest and the map current.
I'm running it right now on the OpenCode Go harness migration — full story later, but
the map already has a transport decision, a session model, and a model budget locked
in, and the remaining tickets are mostly execution. The map lives at
.scratch/opencode-go-harness/map.md with a runbook beside it.
Meta note: this note was written by the agent running on Big Pickle, OpenCode's
free model (opencode/big-pickle) — a decent data point that a free model can write
coherently about a planning tool.
Blistered cherry tomatoes and garlic collapse into a full pasta sauce in twenty minutes — no peeling, no seeding, finished with butter and pasta water.
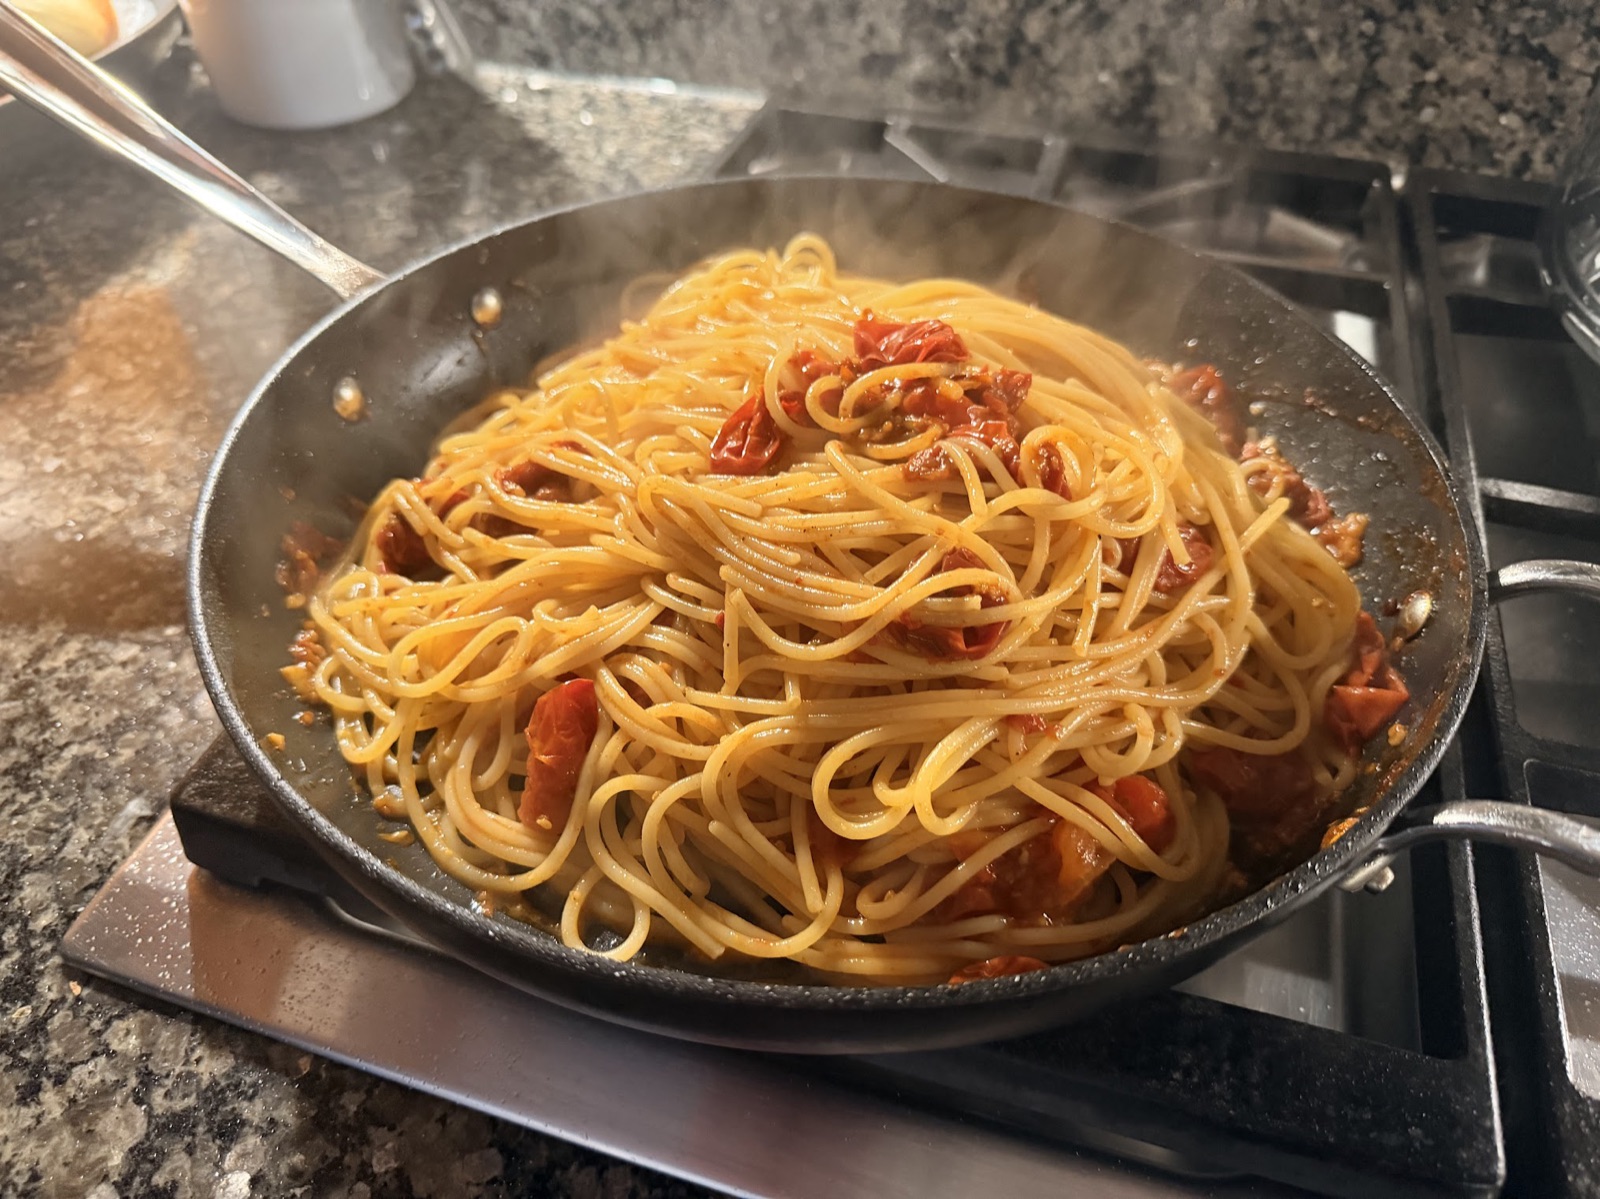 Read recipe
I added a fifth model to mager-bench today and found a bug in the benchmark itself. The bug is more interesting than the model.
GPT-OSS 120B — OpenAI's open-weights model, served on Groq's free tier. The board was two Anthropic models, one Meta, one Google, so this is the first OpenAI-lineage model on it and the first free-tier model that reasons before answering. Total API cost, again: $0.
Getting it running took three fixes, two of them token accounting again:
max_tokens, so a thinking model needs headroom or its answer gets cut mid-implementation.reasoning_format: "parsed" keeps chain-of-thought out of the response body, but it's a Groq-only parameter — the OpenAI SDK rejects unknown top-level kwargs, so it has to ride in extra_body. Miss this and all 13 challenges fail with an unhelpful TypeError.max_tokens together, and rejects over-budget requests outright with a 413 rather than throttling them. So you can't just ask for a big budget and retry.That last one turned out to matter far beyond one model.
Three of my challenges ask for a whole app in a single file: a Doom-style raycaster, a Vegas slot machine, a REST API client class. Every model scored near zero on all three. In an earlier note I wrote that the free models "collapse on the big signature challenges" and left it there, as if that were a fact about the models.
It was a fact about my harness. Every model was getting 2048 output tokens. A working raycaster does not fit in 2048 tokens. I wasn't measuring whether models can build Doom; I was measuring whether they can build Doom in 2048 tokens, and the answer is no for the same reason it would be no for a human handed a 30-line budget.
The fix is per-challenge budgets: doom and slots get 7000 tokens, api-client gets 4096, and the other ten stay at 2048 because they never came close to the cap. That last detail is what made the fix cheap — the ten unaffected challenges keep their existing scores, so I only had to re-run three challenges across five models instead of the whole board.
7000 isn't a round number I liked. It's the largest budget the tightest free tier on the board can actually accept, which is that 8000 TPM ceiling minus the prompt. The slowest model in the fleet sets the speed limit for everyone, because the alternative is giving different models different budgets and calling the scores comparable.
Mostly nothing, and that's the interesting part.
3.4× the budget produced 3–4× longer answers — Haiku's raycaster attempt went from 6,500 characters to 24,000. And every single model still ran out mid-file. Every response tail ends mid-expression: const time, for, Set. Nobody finished.
Score ranges across all five models, before and after:
| Challenge | Before (2048 tok) | After (7000 tok) |
|---|---|---|
| doom | 0.0 – 1.0 | 0.0 – 1.0 |
| slots | 0.0 – 2.3 | 0.0 – 0.7 |
| api-client | 1.7 – 7.0 | 1.7 – 7.7 |
So the scores were roughly right, for entirely the wrong reason. A 70%-complete raycaster and a 25%-complete raycaster both score ~0 against a rubric that asks "is it a working game," which meant a real harness bug was invisible in the numbers. This is the part I'd want to know about someone else's eval: the metric didn't move when the bug was introduced, so it couldn't move when the bug was fixed either. Watching the scores would never have surfaced it. I found it by reading the raw responses and noticing they all ended mid-expression.
Gemini 2.5 Flash fails differently and more honestly: given 15,000 tokens it produced 2,000 characters of prose describing the raycaster it was about to write, then got cut off mid-sentence. It spent its budget thinking and narrating instead of emitting code.
The uncomfortable conclusion is that doom and slots may not be measurable on a free-tier board at all. A one-shot raycaster needs more output tokens than Groq's free tier can physically produce. Either I scope the prompts down to something completable in ~7000 tokens, or I accept that those two challenges only discriminate at the top of the market while everything else scores zero. I haven't decided which, but a prompt that no model on the board can finish isn't discriminating between them, and a column of zeros is not a measurement.
The re-run also caught bad data that had been sitting on the published board. Sonnet 4.6's slot-machine score of 2.3 came from a zero-character response, scored by llama-3.3-70b rather than the board's locked claude-sonnet-5 judge — a stale row from before I pinned the judge. An empty answer had been quietly earning points. The board now audits clean on both counts: no empty responses, no rows scored by the wrong judge. That check runs as part of publishing now, since the only reason I caught it was going looking.
And the leaderboard flipped:
| Model | Tier | Avg |
|---|---|---|
| GPT-OSS 120B | free | 6.4 |
| Claude Sonnet 4.6 | paid | 6.2 |
| Claude Haiku 4.5 | cheap | 6.2 |
| Llama 3.3 70B | free | 5.6 |
| Gemini 2.5 Flash | free | 5.2 |
A free open-weights model is now top of my board. I want to be careful about how much that means: 6.4 versus 6.2 on single runs with no repeats is inside the noise, and part of the gap is Sonnet losing those inflated points from the empty-response row. This is not "open weights beat Claude." It's "on thirteen tasks I picked, scored once each by a Claude judge, they're indistinguishable" — which is still a real result, and cost nothing to produce.
The related change: the leaderboard now shows correctness, quality, and documentation as separate columns instead of one average. That immediately paid for itself. GPT-OSS has the best code-quality score on the board while ranking third on correctness — it writes clean code that's more often subtly wrong. A single averaged number hid that completely, and it's the most useful thing the board has told me all month.
Claude Code 2.1.219 shipped three changes worth pulling out of the changelog.
Opus 5 (claude-opus-5) is now the default Opus model, with a 1M context window. The context number is the part that matters for how I actually use it. My always-on session runs for days at a time, and the thing that used to end a session wasn't the task getting hard — it was the context filling up with tool output from work that was already finished.
Fast mode now applies to Opus 5 and Opus 4.8. Worth being precise about what this is, because the name invites the wrong assumption: fast mode is still Opus, with faster output. It isn't a silent downgrade to a smaller model. Toggle it with /fast.
Subagents can spawn nested subagents, up to depth 3 by default. This is the one that changes my setup. I run a principal-agent pattern — one always-on session on a Mac mini in Chicago that dispatches per-product subagents for magerblog, beatbrain, prxps, loooom, and kotsu. Until now that tree was two levels: the principal delegates once, and whatever it delegated to had to finish the job alone. A subagent that needed a code review or a scraper check had to do it inline.
The honest tradeoff: every level of nesting is another process with its own cold-start context, re-deriving things the parent already knew. Depth 3 is a budget, not a target. The failure mode isn't running out of levels — it's a tree where the leaves are solving the wrong problem confidently, and the root has no way to tell.
It lines up with the unhobbling shift from earlier this week. The model gets trusted with more judgment; the harness gets room to build deeper structures. Both bets are that the thing at the bottom of the tree can read the room.
Anthropic deleted 80% of Claude Code's system prompt for Opus 5 with no measurable loss. They called it unhobbling. Here's what that means for your harness.
Read articleBlock's open-source Nostr workspace puts people and agents on the same cryptographic footing — and lands at the end of a long chain of thinking about where always-on agent infrastructure should actually live.
Read articleUber HQ, San Francisco, CA
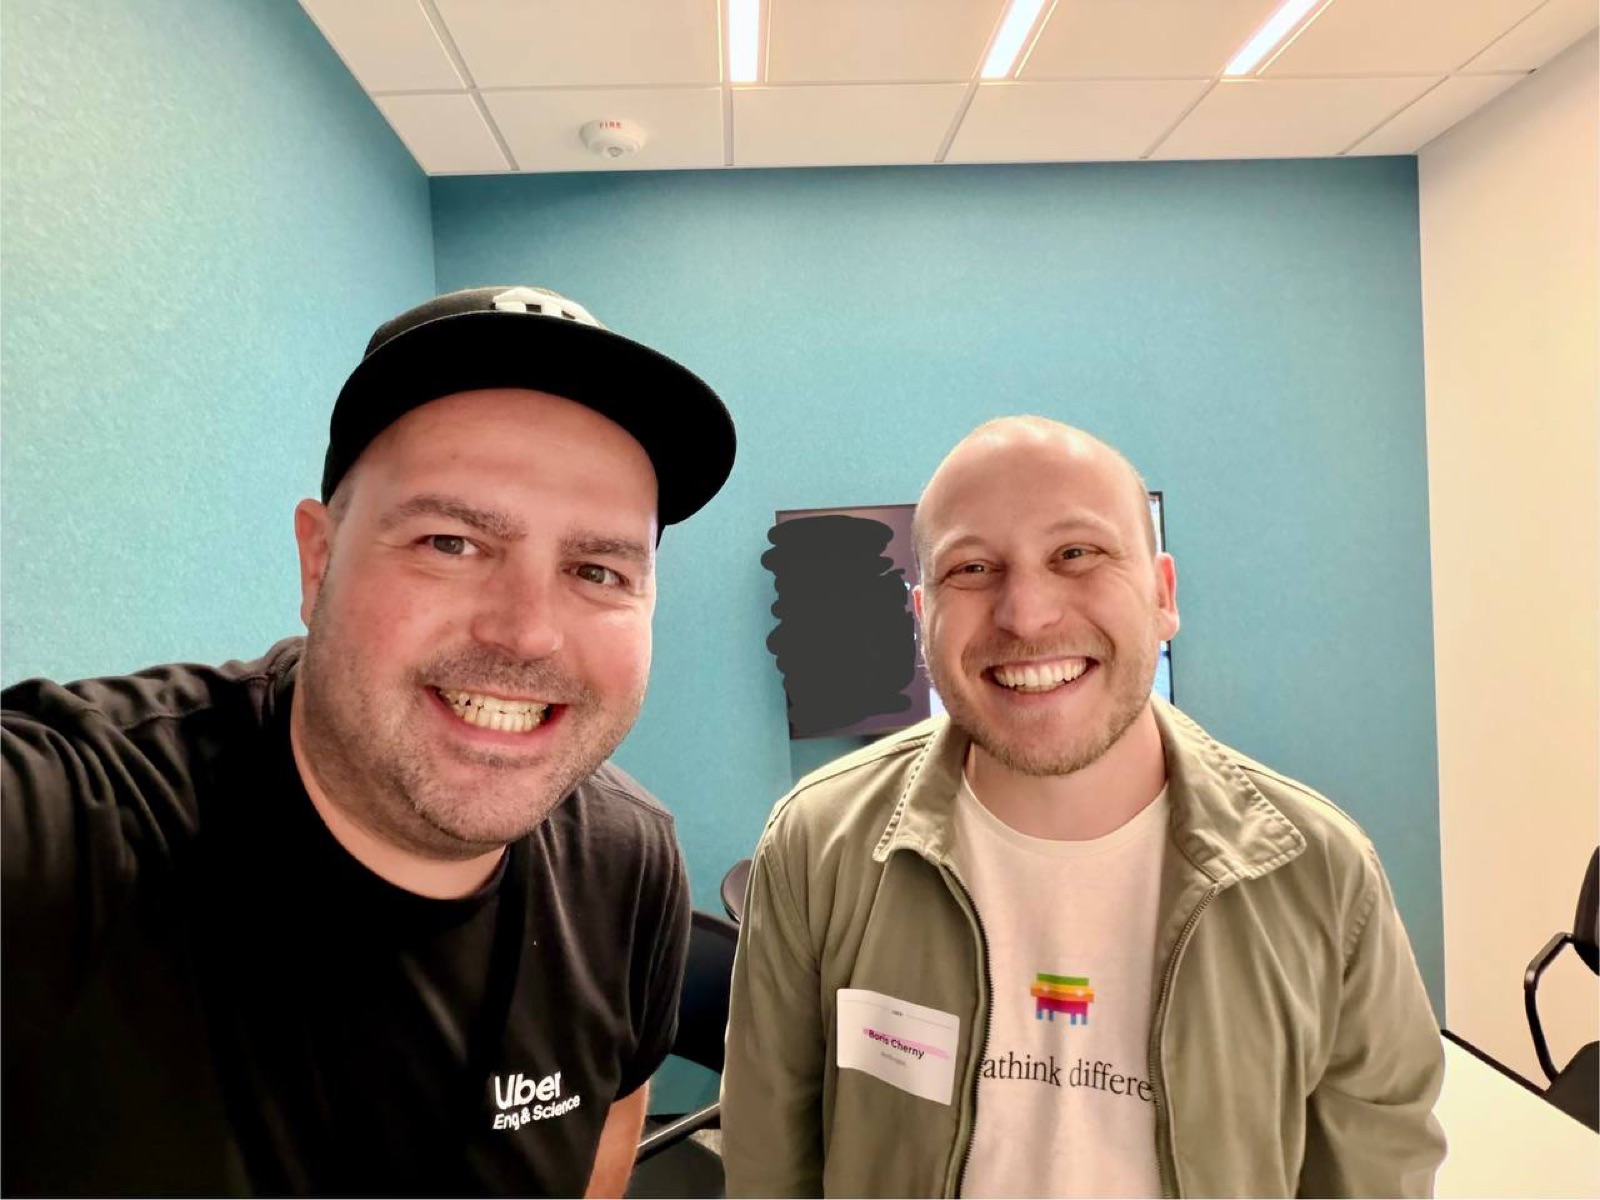
Achievement unlocked: meeting Boris Cherny at Uber HQ.
Wrigley Field, Chicago, IL
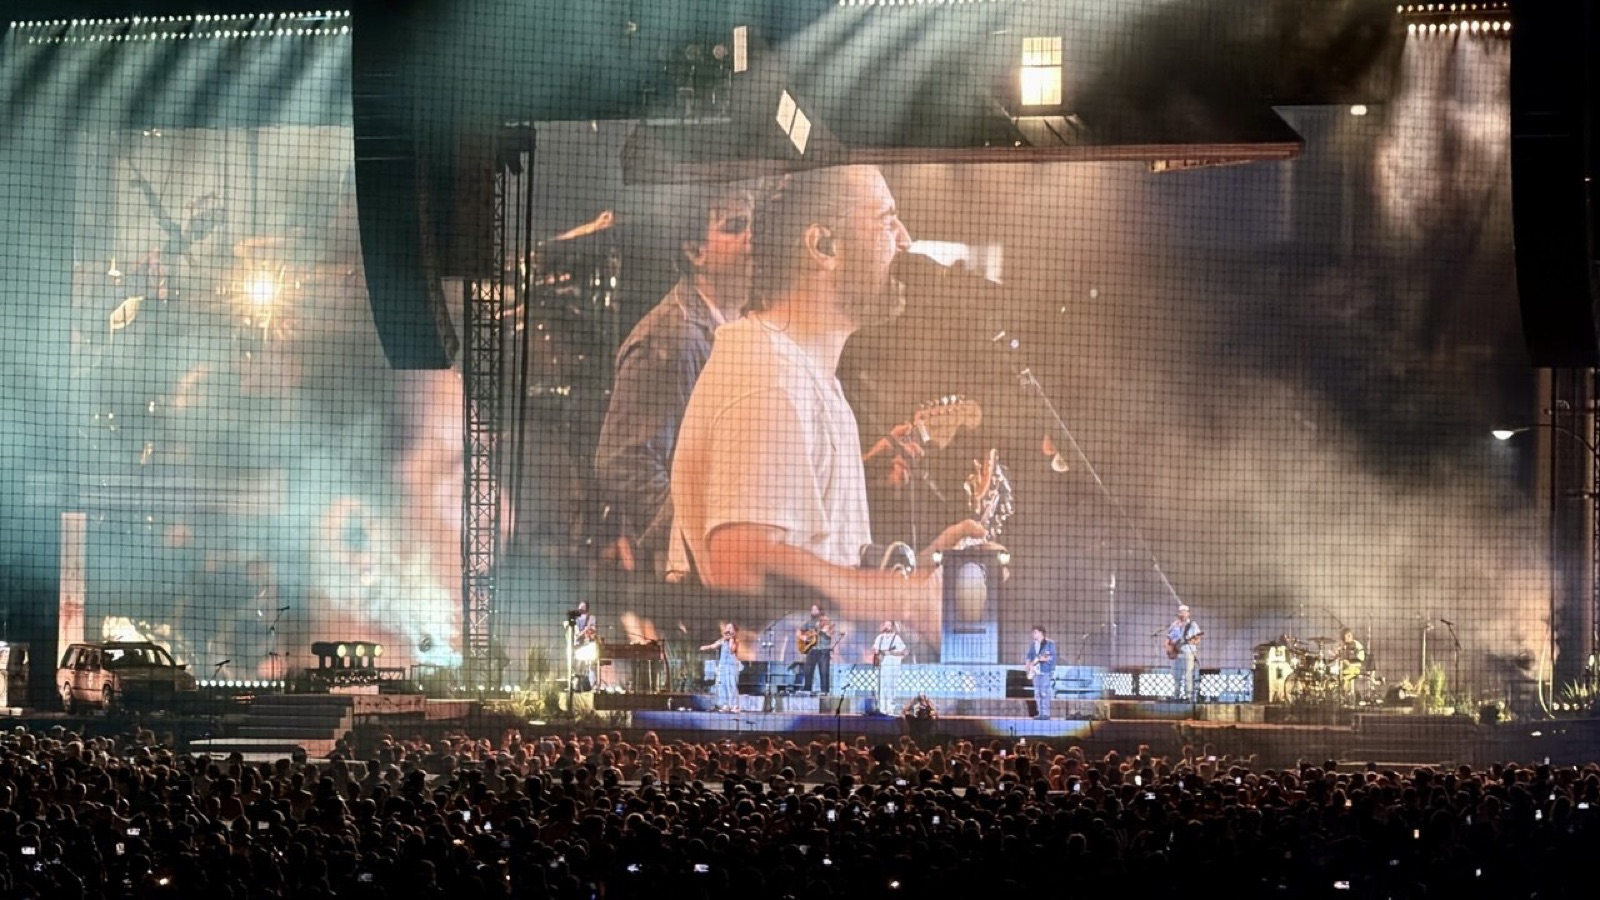
Noah Kahan at Wrigley.
Quick update on mager-bench. Three things happened today: the leaderboard got its first free models, two real eval-engineering bugs surfaced and got fixed, and every run is now traced end to end.
I added Llama 3.3 70B via Groq's free tier and Gemini 2.5 Flash via Google AI Studio's free tier. Total API cost for the model calls: $0.
One wrinkle: I set out to add Gemini 2.0 Flash, but Google has fully retired it — the API 404s with "no longer available." 2.5 Flash is the free-tier successor, so that's what's on the board.
Both bugs came from the same place — models that think by default, and token budgets that didn't account for it.
The judge crashed before scoring. The judge is Claude Sonnet 5, which thinks by default, and its token cap counted thinking and verdict together. Sometimes it spent the entire budget thinking and died before emitting a score. Fix: parse the response's text blocks properly and give the judge a much bigger budget.
Gemini scored zero on everything. Gemini 2.5 Flash also thinks by default, and its thoughts counted against the same output budget as its answer. Its first run produced ~300-character truncated stubs, which the judge correctly scored 0. Fix: give thinking its own headroom on top of the visible-answer budget, then re-run.
If you're building evals in 2026, this is the class of bug to expect. The model isn't bad; your token accounting is.
Final board across 13 challenges, judged by Claude Sonnet 5:
| Model | Tier | Avg |
|---|---|---|
| Claude Haiku 4.5 | cheap | 6.7 |
| Claude Sonnet 4.6 | paid | 6.3 |
| Llama 3.3 70B | free | 5.5 |
| Gemini 2.5 Flash | free | 5.4 |
The free models hang surprisingly close to the paid ones on bread-and-butter tasks — Llama scored 9.7 on fizzbuzz and 8.7 on refactor. But both collapse to roughly 0 on the big signature challenges (the doom raycaster, the slot machine). And Llama has one genuine superpower: speed. About 1.9s average response on Groq, versus 22–24s for everything else.
Every bench run is now instrumented with Arize AX via OpenTelemetry/OpenInference: one CHAIN span per model×challenge with the scores attached as metadata, auto-instrumented Anthropic and OpenAI calls nested underneath, and each result row stores its trace_id. Run detail pages on the dashboard deep-link straight to the trace in Arize, so when a score looks wrong I can open the exact conversation that produced it.
That's the loop I wanted: benchmarks are effectively free now if you're willing to debug thinking-token budgets, and observability is what closes the loop when the numbers look off.
bench.mager.co
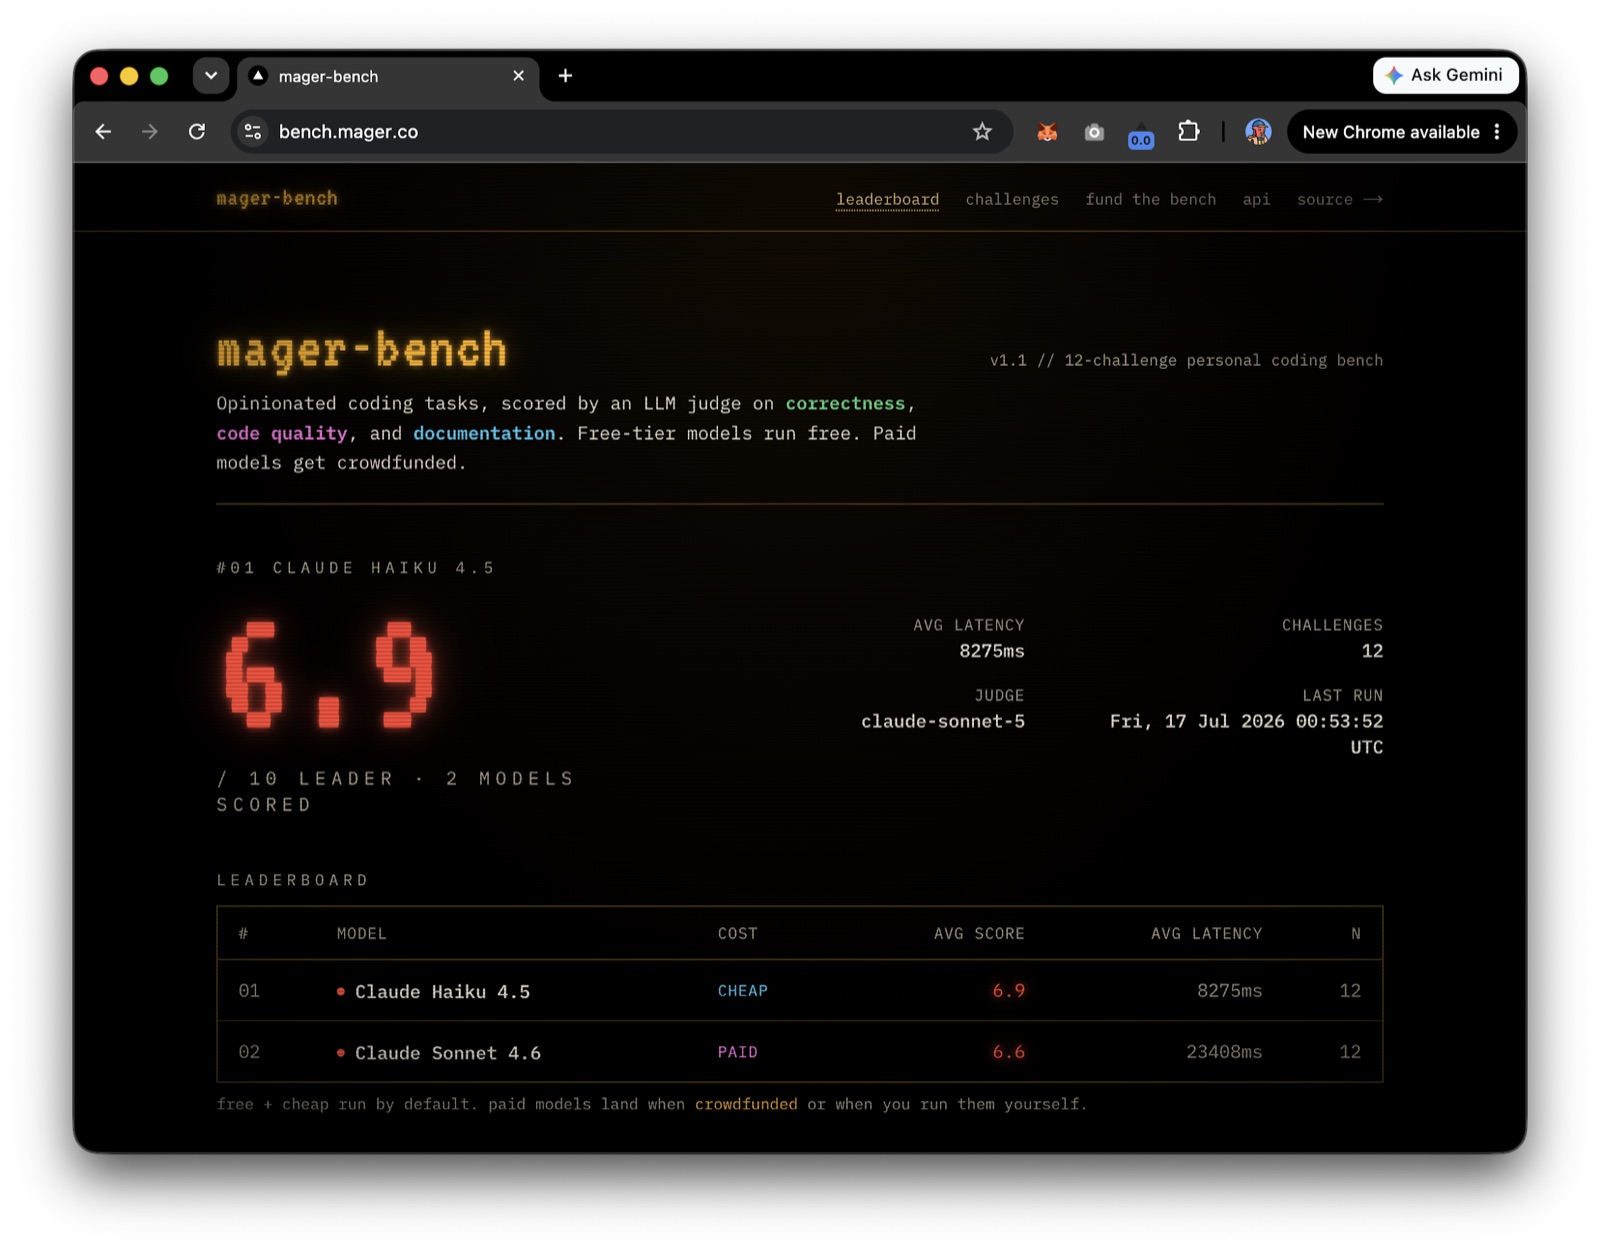
The personal coding model benchmark dashboard has its own domain now. The original post explains what mager-bench is.
Simon Willison's pelican benchmark is one prompt — "Generate an SVG of a pelican riding a bicycle" — and the quality gap between models is immediately obvious when you look at the output. I wanted mager-bench to have its equivalent: one iconic, hard prompt where runnable output makes the difference self-evident.
The new doom challenge asks a model to build a Doom-style first-person raycasting FPS engine in a single HTML file, no external libraries. Open the file, play it.
The raycaster is not a Doom-themed prompt — it is literally Doom's engine. DDA raycasting, fish-eye correction, perspective-correct texture mapping, distance shading, a 16×16 map with rooms and dead ends, WASD + Pointer Lock mouse-look, AABB collision detection, a door that opens on E, an exit with a LEVEL COMPLETE timer, Z-buffer, minimap, FPS counter. All procedural — no images, no canvas assets loaded at runtime.
I grew up playing Doom. The technical core — casting rays through a 2D grid to fake a 3D world on underpowered hardware — is one of the most elegant ideas in the history of games. Models that actually understand the math produce something you can walk through. Models that fake it produce a gray box or a broken canvas.
The gap is instant and obvious. That's the benchmark.
All challenges are on GitHub.
mager-bench v1.1 restructures the bench around cost. Default runs now use free models — Llama 3.3 70B and 3.1 8B through a new Groq adapter, plus Gemini Flash — and the judge defaults to a free model too, so a full 12-challenge leaderboard costs $0 and no longer requires an Anthropic key.
The README has carried the same two caveats since day one: the judge is a model too (by default, Claude grading Claude), and single-run variance is real. Both now have flags instead of apologies. --runs 3 reports mean ± stddev, so a score is a distribution rather than one roll. --judges gemini-2.0-flash,llama-3.3-70b averages a judge panel, so no model grades its own family alone.
export GROQ_API_KEY=... GEMINI_API_KEY=...
python bench.py --tier free --runs 3 \
  --judges gemini-2.0-flash,llama-3.3-70b
The expensive seats — Opus, GPT-4o, Sonnet — move to a public wishlist. There's a live /fund page and a FUND.md; Buy Me a Coffee is the working rail today, with GitHub Sponsors to follow. One rule either way: dollars only buy API tokens for published evals. Every funded run ships its raw responses and scores in results.json.
"Ships its raw responses" is now literal: every score on the dashboard links to a trace page with the exact prompt, the model's full response, and the judge's notes for each run. Haiku's 0.7 on doom stops being a number and becomes a readable failure.
Free tiers keep the leaderboard always on; crowdfunding unlocks the head-to-heads people actually argue about. All twelve challenges are on GitHub.
mager-bench expanded from 5 to 11 challenges. The four new ones cover territory the original set glossed over — testing discipline, debugging skill, async Python, and SQL fluency.
test-writing gives you a parse_duration() function and asks for a proper pytest suite using @pytest.mark.parametrize and pytest.raises. The interesting signal isn't whether models know pytest syntax — they all do — it's whether they parameterize across edge cases or just write three happy-path tests and call it done.
debug is a broken top_words() implementation with three distinct bugs. No stack trace, no error message — just wrong output. It tests careful reading more than raw code generation. Models that reach for the REPL in their heads before editing tend to do better here.
async-fetch asks for concurrent aiohttp requests with a per-request timeout and exponential backoff retry. It's a proxy for "can the model reason about failure modes at the call site, not just happy-path concurrency."
sql is a PostgreSQL query over an orders/customers schema that requires CTEs and window functions to answer cleanly. Most models can write either; the challenge is knowing when a window function is the right tool instead of a subquery.
Two more just landed: go-test asks for a table-driven WordCount test file using t.Run subtests and a benchmark — the idiomatic Go testing pattern that most models know in theory but often write awkwardly. elixir-test asks for an ExUnit suite with describe blocks and assert_raise, including a unicode string case that trips up anything relying on byte counts instead of String.length/1.
All eleven challenges are on GitHub.
A Skill is packaged know-how. An Agent is that know-how put to work autonomously. Subagents are where the work scales past what any single context can hold.
Read articleOpenRouter lets you pick a different model for every step in a pipeline. Here's how to use Fable for planning and Sonnet for execution — with runnable TypeScript.
Read articleInstead of reading someone else's leaderboard, build a small set of tasks you actually care about and run them yourself every time a new model drops — Simon Willison's SVG pelican test, but for code.
Read articleIn March I wrote the theory. Zach from Warp shipped the implementation. Here's how a working cloud factory maps to the architecture I laid out.
 Read article
Most evals talk is about grading model output. Skill evals grade a different thing — the SKILL.md artifact you wrote — with real numbers from SkillsBench to back it up.
Read articleskill-evals is a small Claude Code plugin for evaluating the skills and agents you build. It came out of reading the awesome-evals PATTERNS playbook and wanting the patterns as something I could run inside a project, not just a reference to nod along to. v0.1 is two skills.
The first, error-analysis, is the unglamorous step most people skip: read 20–100 real traces, write a one-line note on the first thing that broke in each, cluster those into a handful of named failure modes, and rank them by frequency × severity. The point is that you can't write a good eval for a failure you haven't seen yet, and generic metrics like "helpfulness" point nowhere. The output is a short taxonomy that tells you what to actually measure — and which failures need a cheap code assertion versus an LLM judge.
The second, build-judge, is the one I learned the most from. Using an LLM to grade subjective things (tone, faithfulness, did-it-follow-the-instruction) is easy; trusting that grader is the hard part. On an imbalanced set — say 90% of outputs are fine — a judge that stamps everything "pass" scores 90% accuracy and catches none of the real failures. So the skill ships a stdlib-only score.py that reports true-positive and true-negative rate separately and gates on both, exiting non-zero below threshold so it drops straight into CI. The rubber-stamp judge fails that gate even at 90% accuracy, which is exactly the trap it's there to catch.
Since then, v0.2 shipped exactly the patterns I'd left out: add-assertions (deterministic check scaffolding), passk (pass@k versus pass^k with the unbiased estimator), synth-data (grounded synthetic sets when you have no traffic), and an eval-runner agent that runs a whole suite and reports honestly. I also did the dogfood — pointing eval-runner at all 124 posts on this very blog. The first pass screamed that zero posts passed every check, which is exactly the kind of number that makes you panic and learn nothing. The honest finding was that my spec was wrong, not the blog: it was grading against categories and a keyword format the real schema never used. Once I fixed the spec, every post came back clean. That's the lesson the whole thing is built to teach — most "failures" are your metric lying, and you only catch it by looking.
If you want the conceptual map behind these patterns rather than the code, I wrote one up: a plain-English tour of the eval types worth knowing.
A small Python voice agent that remembers the thread, streams Claude's reply to the terminal, and speaks it aloud through ElevenLabs — no ffmpeg, just afplay.
Read articleDefine your agent in a directory, deploy it to Vercel's cloud with one command, and access it from anywhere. Months in, Eve has grown a platform around that model — capability registry, sandbox, subagents, agent-to-agent calls, MCP, evals — and my agent is still live, driven remotely from the eve TUI.
Read articleA Skill is reusable know-how Claude reaches for on its own. A Workflow is an explicit pipeline you wire up and control. Here's the difference, what you can build with each, and when to reach for which.
Read articleLoooom is v1.0 — tagged and released on GitHub. The shape hasn't changed since the pivot post: fifteen curated non-technical skills, each scored against a written rubric. What v1.0 adds is the layer of testing that was missing.
The two rubric gates judge the skill text. The new third gate runs each skill the way an agent actually would — SKILL.md as the system prompt — and unit-tests its Agent Behavior contract with promptfoo: hook has to make you say what the song is about in one sentence before writing anything, stack has to kill the 23% credit card before entertaining the crypto bet, focus has to send your phone to another room. Thirty tests, two per skill, deterministic assertions plus an LLM rubric, all on Groq's free tier.
The whole harness still costs $0 — judge and tests both run on Groq's free tier. The price shows up in a different currency: run the suite three times back-to-back and you blow through the tokens-per-minute cap, and everything crawls behind HTTP 429s. Promptfoo's cache makes that mostly painless (passing tests don't re-run), but a free eval stack rations your iteration speed instead of your wallet. For a project this size, that's the right trade.
The first run came back 27/30, and the failures were the educational part. Two were the tests' fault, not the skills': story and frame were correctly following their own "make them name the one thing first" contract while my rubrics demanded the whole lecture in turn one. The third was a token cap truncating train before it reached progressive overload. Behavioral tests don't just check the skills — they force you to decide what the skill is actually supposed to do on the first turn.
The audit also closed an embarrassing loop: voice had been shipping without a worked example — the one skill not practicing what it preached, and the spec gate had been flagging it since day one. Fixed in v1.0.
I ran this whole launch with Claude Code on Fable, Anthropic's new model — the skill audit, the test suite, the release, and this note. First project I've shipped with it.
Three real ingredients — pecorino, pepper, pasta water — plus a knob of butter for insurance, tossed into a glossy sauce that never breaks.
 Read recipe
How I worked with Claude through five rounds of image generation to design a logo for my Japanese learning app — and ended up inventing a kanji that hides a smile.
 Read article
Lady Gregory's, Andersonville, Chicago, IL

Table card at Lady Gregory's, in the heart of Andersonville. A whole vocabulary of the month, set in rainbow.
A plain-English walkthrough for setting up your own always-on AI assistant on a Mac mini — OpenClaw, Google Gemini, and Tailscale — written for a first-timer.
Read articleFenway, Boston, MA

Sox game with Dad and Matt.
I run a Claude Code agent on a Mac mini in Chicago that I reach over Telegram. The hard part isn't the agent, it's keeping it up without me — across crashes, model swaps, and the occasional reboot. The fix is layered supervision, where each layer owns one kind of failure:
run.sh loops the agent and watches its exit code. An in-session model
switch exits with code 42; the loop sees that and relaunches on the new model.
Any other code stops the loop and hands control up.LaunchAgent with RunAtLoad starts the tmux
session at login (so it survives a reboot), and a StartInterval watchdog
re-checks every couple of minutes and rebuilds the session if it's gone.The thing I keep relearning: "restart it when it dies" is not one job. A reboot, a crash, and an intentional model swap are different failures, and each wants a different layer to catch it. Pile them all into one script and it's brittle; separate them and the whole thing just stays up.
I love OpenClaw. I hate that it doesn't run on my Claude Pro subscription. Turns out Claude Code, with the Telegram channels plugin and one CLAUDE.md, is the same harness — minus the daemon, the API bill, and the second LLM provider. Here's the actual recipe, ported from a hotel in Tokyo to a Mac mini in Chicago in forty minutes.
Read articleA curated collection of high-quality skills for people who don't code — and an experiment in what actually makes a skill good.
 Read article
A month that turned the "agentic turn" from talking point to shipping product. Google I/O, Opus 4.8, a $65B raise, and the infrastructure race to run your agents 24/7.
Read articleA five-ingredient Japanese-style spaghetti — butter, tamari, and parmesan tossed with hot pasta and finished with green onion. The wafu pasta I kept eyeing in Tokyo, made at home in ten minutes.
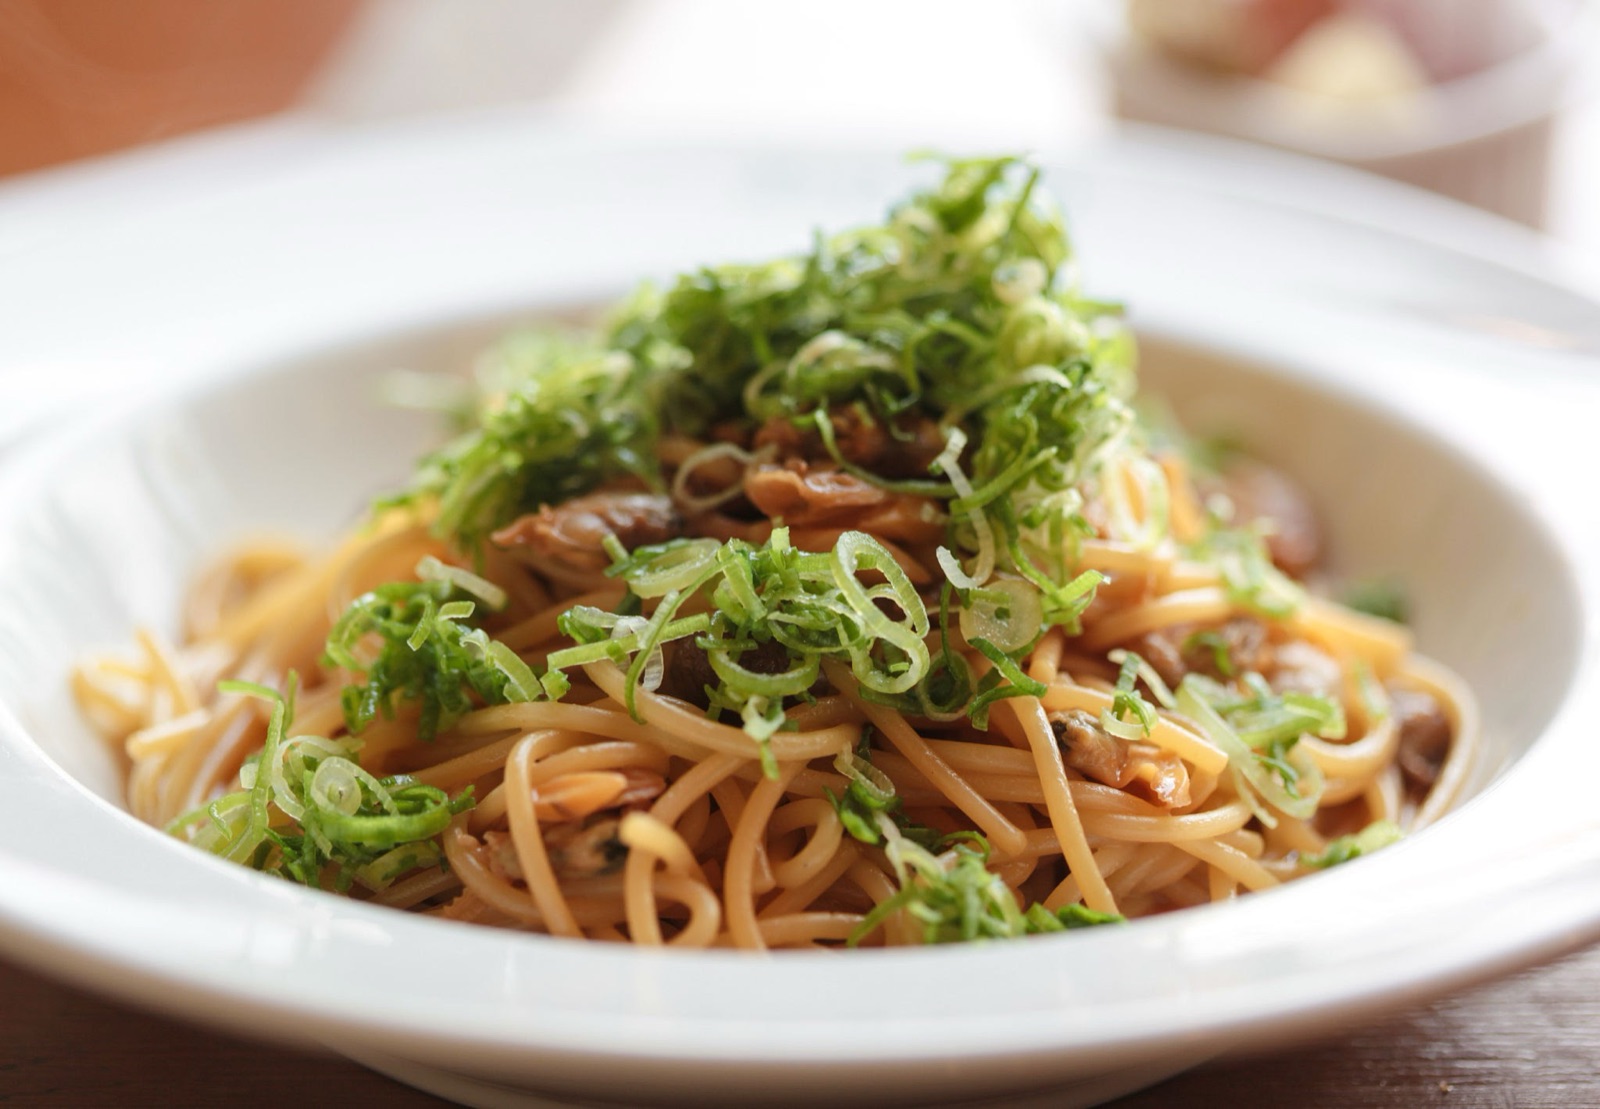 Read recipe
Microsoft's SkillOpt is the first paper to treat agent skill files as trainable parameters — propose an edit, evaluate on held-out examples, accept only on strict improvement. Here's what it found and what it means for teams building with agents.
Read articleOpenHuman is a desktop-first agentic assistant with persistent memory, 118+ OAuth integrations, and a token compression layer. Here's what it does and how it fits alongside an existing Claude Code harness.
Read articleKarpathy's four rules for agentic coding are worth reading — having them written down in a shared format is a useful starting point for anyone building with Claude Code.
Read articleHow I moved magerbot's brain from @-imported markdown files into gbrain's Postgres-native semantic memory layer — what broke, what the gotcha was, and why the context model is fundamentally better.
Read articleHanshin Tigers vs. Chunichi Dragons at Koshien Stadium — the right-field cheering section, uriko beer vendors, 7th-inning balloons, and a walk-off home run to win it.
 Read article
Garry Tan open-sourced gbrain — a self-wiring knowledge graph for AI agents. Here's what it is, why we moved to it, and exactly how we did the migration from flat markdown files.
Read articleWe missed the original ticket sale, got rescued by a tour, and spent an afternoon learning how much more fun sumo is when someone helps you understand what you're watching.
 Read article
I built a 200-line harness called conseiller to test Anthropic's new advisor tool — a fast executor model that consults a stronger model mid-generation. Two days later Anthropic shipped Claude Managed Agents, Multi-agent Orchestration, Dreams, Routines, and Remote Agents. Here's both halves: what I built and what they shipped, and how the pieces fit together into something a lot like OpenClaw.
Read articleI built a Go Bubble Tea starter for local model servers, used Gemma 4 through llama.cpp, and split the TUI into llocal.
 Read article
I'd been seeing chatter about Hermes Agent from Nous Research, so I installed it locally and put it to work on this blog. Notes on the pitch, the SOUL.md system, and what it actually felt like to use.
 Read article
A practical explainer for both developers and everyday Claude users: what prompt caching is, what gets reused, what breaks it, and how to make long sessions cheaper and faster.
Read articleA simple set of habits I use to keep long AI coding sessions from getting bloated: better one-shot prompts, matching model and thinking level to the job, understanding cache behavior, and using cheaper orchestrators when it makes sense.
Read articleA fennel-forward Italian spice blend that turns any ground meat into proper sausage
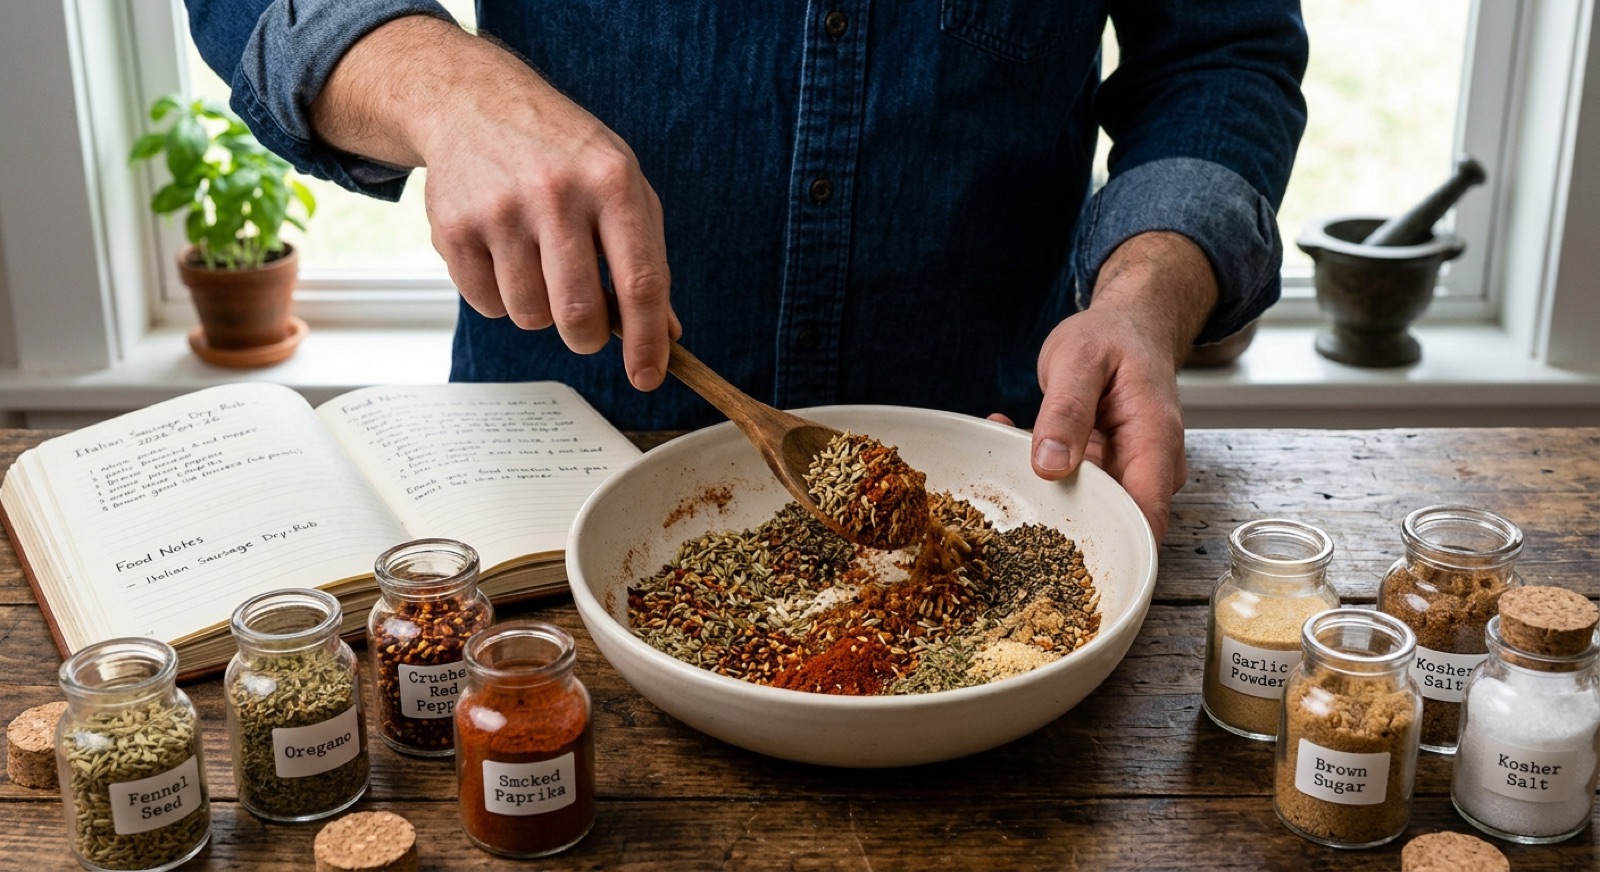 Read recipe
I reverse engineered several of my own sites into DESIGN.md files to see how much of a design system can actually be described, and why writing down design intent might be more reusable than it looks.
Read articleA practical tour of Claude Code flags that are easy to miss but genuinely useful once you move past the default interactive loop.
Read articleA bright, high-impact rice finished with garlic, lots of cilantro, and fresh lime juice added after cooking.
 Read recipe
Anthropic shutting down OAuth-based Claude Code access forced my hand. Here's how I moved OpenClaw to OpenAI Codex, why Codex makes more sense inside a real agent harness than it did on its own, and why brainpack changes the switching cost.
Read articleThe Y Combinator CEO open-sourced his entire Claude Code workflow. Here are the 10 skills worth knowing — including why office-hours should be the first thing you run on any new idea.
Read articleI tested Anthropic's official Claude plugins for knowledge workers. Here are the 10 that deliver the most value for PMs, engineers, sales teams, and operators.
Read articleI used Gemini to write a Loooom skill, installed it in Claude Code, and got a full audio analysis report on a 37-second piano recording of Espresso. Turns out AIs teaching AIs new senses is a surprisingly powerful pattern.
 Read article
I rebuilt the beatbrain backend in an afternoon. Parallel fetching, Firestore caching, and a podcast discovery engine that indexes 100+ categories. Here's the whole story.
Read articleI built a Japanese learning site in a morning because I wanted something I could pull up on my phone and just look at characters. Here's how Gemini wrote the prompt and magerbot built the whole thing.
Read articleDogfooding Karpathy's autoresearch pattern on my own skill marketplace. How I'm using evals and tight feedback loops to make the learn-anything skill measurably better.
Read articleClaude Code's new channels feature lets you push messages from Telegram and Discord into a running session. Here's how it works, why mobile access changes everything, and how I'd wire it into my projects.
Read articleEveryone's talking about building a software factory. Here's where the term came from and how engineers can start thinking about building one.
Read article12 hours before my bracket was due, I used Gemma-3-27b to generate unique insights for all 32 first-round games. Here's what the AI found — and what it got wrong.
 Read article
4lb corned beef, mini carrots, cabbage, potatoes — braised low and slow in a covered Dutch oven. The St. Patrick's Day comfort food move.
 Read recipe
LangChain just dropped Open SWE — an open-source framework for building internal coding agents like Stripe's Minions, Ramp's Inspect, and Coinbase's Cloudbot. Here's what it is, how it works, and how to customize it.
Read article3 ripe bananas, brown sugar, walnuts, and a scoop of plain yogurt — baked at 325° convection for the moistest loaf you'll make.
 Read recipe
mager.co is no longer just a blog. It's a corporation. Here's how I staffed it with 145 specialized AI agents using agency-agents and OpenClaw.
Read articleAndrej Karpathy open-sourced a loop where AI agents run experiments, measure results, and keep what works — all while you sleep. Here's how the pattern works and how I'm applying it beyond LLM training.
Read articleThe Claude Agent SDK gives you the same engine that powers Claude Code, fully programmable. Here's how to build a custom TUI with it in 10 minutes.
 Read article
I built an MCP server for Loooom so AI agents can search, explore, and install Claude Code skills without ever leaving their context.
Read articleHow a weekend contribution to OpenClaw replaced my autossh aliases with `openclaw tunnel up/down/status` — and what I learned reading a real codebase to do it right.
Read articleStop stuffing your prompts. OpenViking gives AI agents a filesystem-native brain — tiered, retrievable, self-evolving context at 91% lower token cost.
Read articleEighty years after Asimov's Three Laws of Robotics debuted, we're building the future he imagined—without the safeguards. What the 'Father of Robotics' got right, where his vision fails, and why 2026's AI alignment problem is harder than fiction.
Read articleI kept fixing the same SEO issues by hand — missing keywords, empty hero images, weak descriptions. So I built a Claude Code skill that audits any blog's frontmatter and runs quality evals.
Read articleLangGraph is the production framework for complex agent workflows. Here's how to build a real-time chat system with persistent state, human-in-the-loop, and multi-agent orchestration.
Read articleLangChain just shipped DeepAgents — a batteries-included agent harness that brings Claude Code's magic to any model. Here's your 10-minute deep dive.
Read articleMost websites beg search engines for attention. I flipped it — Loooom is machine-first, humans secondary. Here's what that actually means in practice.
Read articlePart 2 of the prompt verification series. We covered output quality testing with promptfoo — now we tackle the harder problem: does your skill even fire?
Read articleA deep dive into the two most powerful tools for building production-grade multi-agent systems — LangGraph's graph-based orchestration and Anthropic's Claude Agent SDK (formerly Claude Code SDK).
Read articleStop re-prompting every AI session. One file. Every AI knows you — and your agents. Introducing ME.md on Loooom.
Read articleI run two AI agents — magerbot handles code and ops, genny runs my life. Inspired by the Agent Communication Protocol, here's how I got them to actually talk to each other. Now with a full TUI built on the Claude Agent SDK.
Read articleI built a second AI agent to manage the parts of my life that code can't fix — exercise, nutrition, travel, and living to 100.
 Read article
Three ingredients, one sheet pan, and a blender. Roasted cauliflower and a whole head of garlic blended into a velvety, dairy-free soup that somehow tastes indulgent.
 Read recipe
A whole chicken browned on the stovetop, then slow-roasted in a Dutch oven over turmeric-saffron basmati rice. Cozy, hands-off, and spectacular for a Sunday.
 Read recipe
Stop shipping AI features blind. Here's everything you need to know about unit testing prompts — from five-minute quick starts to CI/CD pipelines, agent workflow testing, and building a regression suite that actually catches breakage.
Read articleSpec compliance tells you if a skill is readable. Evals tell you if it's actually good. Here's how we added a public quality score to every Loooom plugin.
Read articleI'm going to Japan in 2 months. Instead of paying for another app, I built a Japanese learning plugin for Claude Code and used it to learn conversational Japanese for free — using Claude Pro I already pay for.
 Read article
How to run OpenClaw on a Mac Mini 24/7, lock it down with Tailscale, and load your agent's brain with brainpack — so your laptop can reach it from anywhere on your tailnet.
 Read article
Your AI agent has memories, skills, and a personality. Here's how to pack it all up and ship it to a new machine — whether you're the human or the agent reading this.
Read articleHow I used the pi-mono toolkit — the same engine behind OpenClaw — to build a free, terminal-based music friend that reads the beatbrain discover feed and recommends what to listen to.
 Read article
A dead-simple one-dish Greek chicken casserole with orzo, feta, spinach, broccoli, sautéed onion, and lemon. Minimal cleanup, maximum flavor.
 Read recipe
Italian sausage, tiny sea shape pasta, crushed tomatoes, kale, and a Parmesan rind simmered into a brothy, deeply savory one-pot soup.
 Read recipe
I analyzed three of my projects, interviewed myself about what makes a UI hot, and packaged it all into a reusable skill for Claude Code.
Read articleA practical guide to building a multi-agent AI system with OpenClaw. One principal agent, multiple specialists, shared skills, and the workspace files that give them personality. Includes real examples from my blog, sports app, and music discovery projects.
 Read article
A cozy Italian-American casserole featuring shredded rotisserie chicken, San Marzano tomatoes, peppers, and mushrooms topped with melted mozzarella.
 Read recipe
A slightly spicy white chile with green chiles, chicken, corn, and hominy.
 Read recipe
A quick and flavorful green curry with chicken and broccoli served over rice - simple weeknight comfort food.
 Read recipe
A delicious fusion of Mexican flavors layered like lasagna, featuring shredded rotisserie chicken, corn tortillas, green & red chile sauce, and plenty of cheese.
 Read recipe
A practical guide to building two-stage AI recommendations: use embeddings for fast retrieval, then small LLMs like Gemma 3 for natural language explanations. The real skill? Curating context, not writing algorithms.
 Read article
A quick, one-pan meal featuring orzo, spinach, peas, and feta. Similar to spanakorizo, this is deeply satisfying but still on the lighter side thanks to all those vegetables.
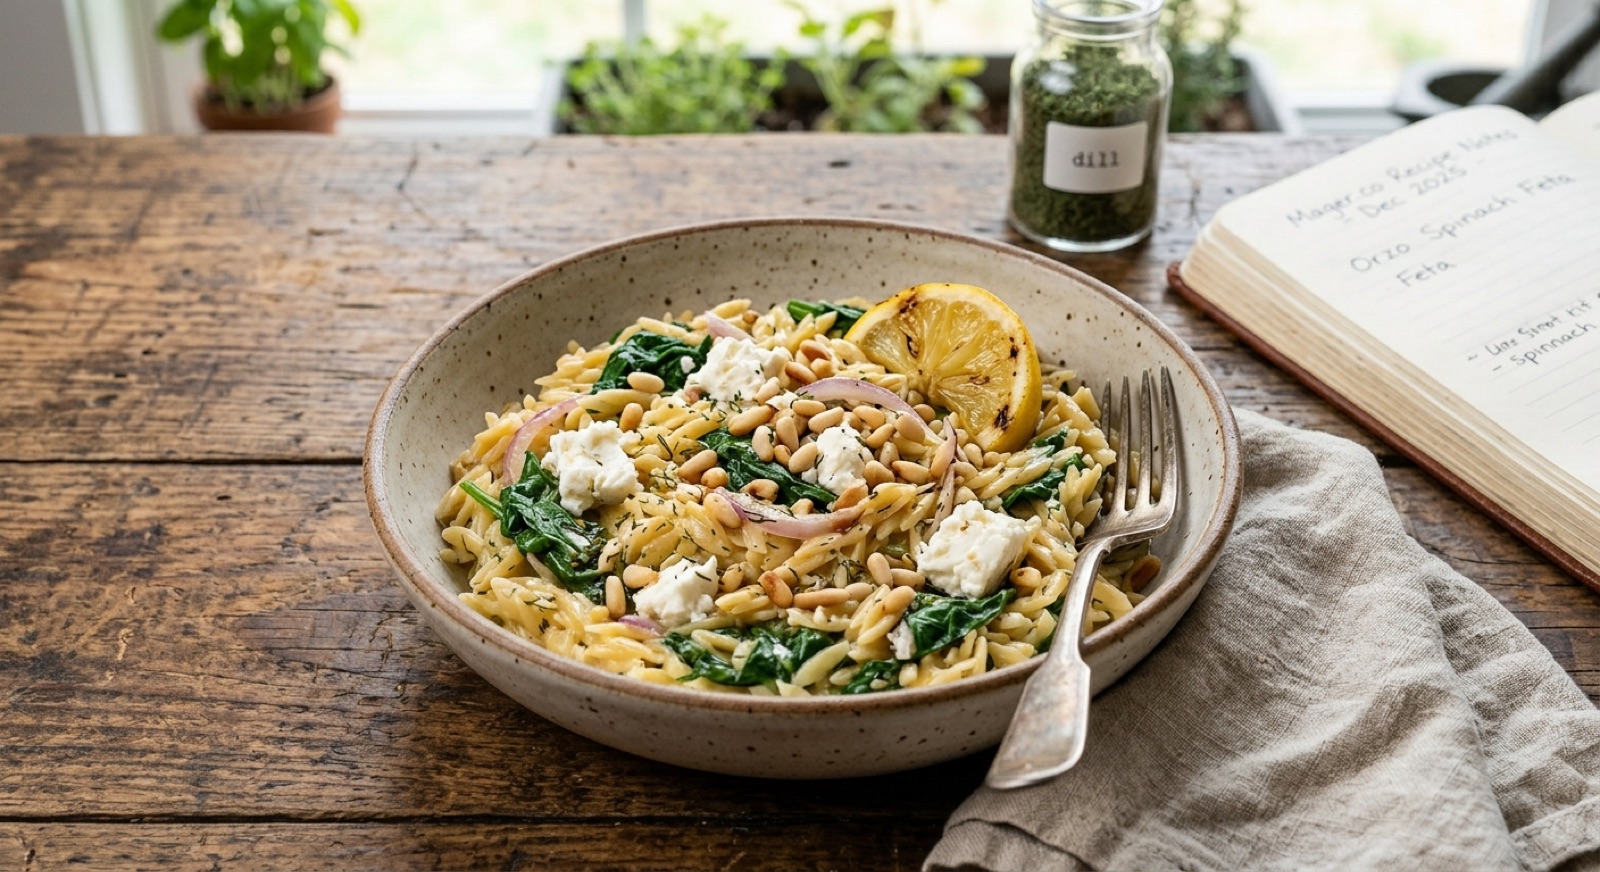 Read recipe
A rich and creamy broccoli cheddar soup with sharp cheddar cheese, perfect for a comforting meal on a cold day.
 Read recipe
A hearty cottage pie made with ground beef, following Alton Brown's method. Perfect comfort food for a cold day.
 Read recipe
beatbrain is a social music discovery app built on Go Fx and Firestore. Find hot new releases, share your favorites, and see what your friends are actually listening to — Spotify meets Last.fm, built from scratch.
 Read article
A beautifully tender pork roast, slow-cooked in savory aromatics with an incredible crust. Works great with pork shoulder or bone-in pork chops.
 Read recipe
A light, comforting soup packed with vibrant flavor and healthy ingredients like butternut squash and lentils. It delivers all the richness of a curry without being heavy.
 Read recipe
A lighter, bright and nutty take on classic meatballs with chicken and pistachios.
 Read recipe
A hearty and warming turkey chili with a deep, smoky flavor from chimayo pepper, perfect for a cozy dinner.
 Read recipe
A reverse sear technique for perfectly crispy skin and juicy meat, every time.
 Read recipe
A foolproof recipe for a perfect medium-rare Tomahawk steak. Seasoned overnight with Holy Cow BBQ Rub, seared hot, and finished with indirect heat on the grill.
 Read recipe
A lighter, summery lasagna using grilled zucchini instead of noodles, with mozzarella, ricotta, and a simple tomato sauce. Optionally spicy with Calabrian chilies.
 Read recipe
Incredibly tender, flavorful pulled pork made easy in a Dutch oven using a sear-first, low-and-slow braising method.
 Read recipe
A taste of Italy anytime, these meatballs will steal the show at any special occasion or a Tuesday.
 Read recipe
My staple mac & cheese, just a few pantry ingredients and a lot of comfort.
Read recipeA creamy and indulgent potato casserole, perfect for holiday gatherings, that will leave you and your guests wanting more every year.
 Read recipe
A staple soup that warms the heart and calms the soul.
 Read recipe
A delicious, healthy soup that will reset your system.
 Read recipe
One of the best soups to kick off the autumn season, a variation that uses chicken sausage
 Read recipe
I had the incredible opportunity to explore a town in Sicily where my ancestors once resided and engage with the local officials.
 Read article
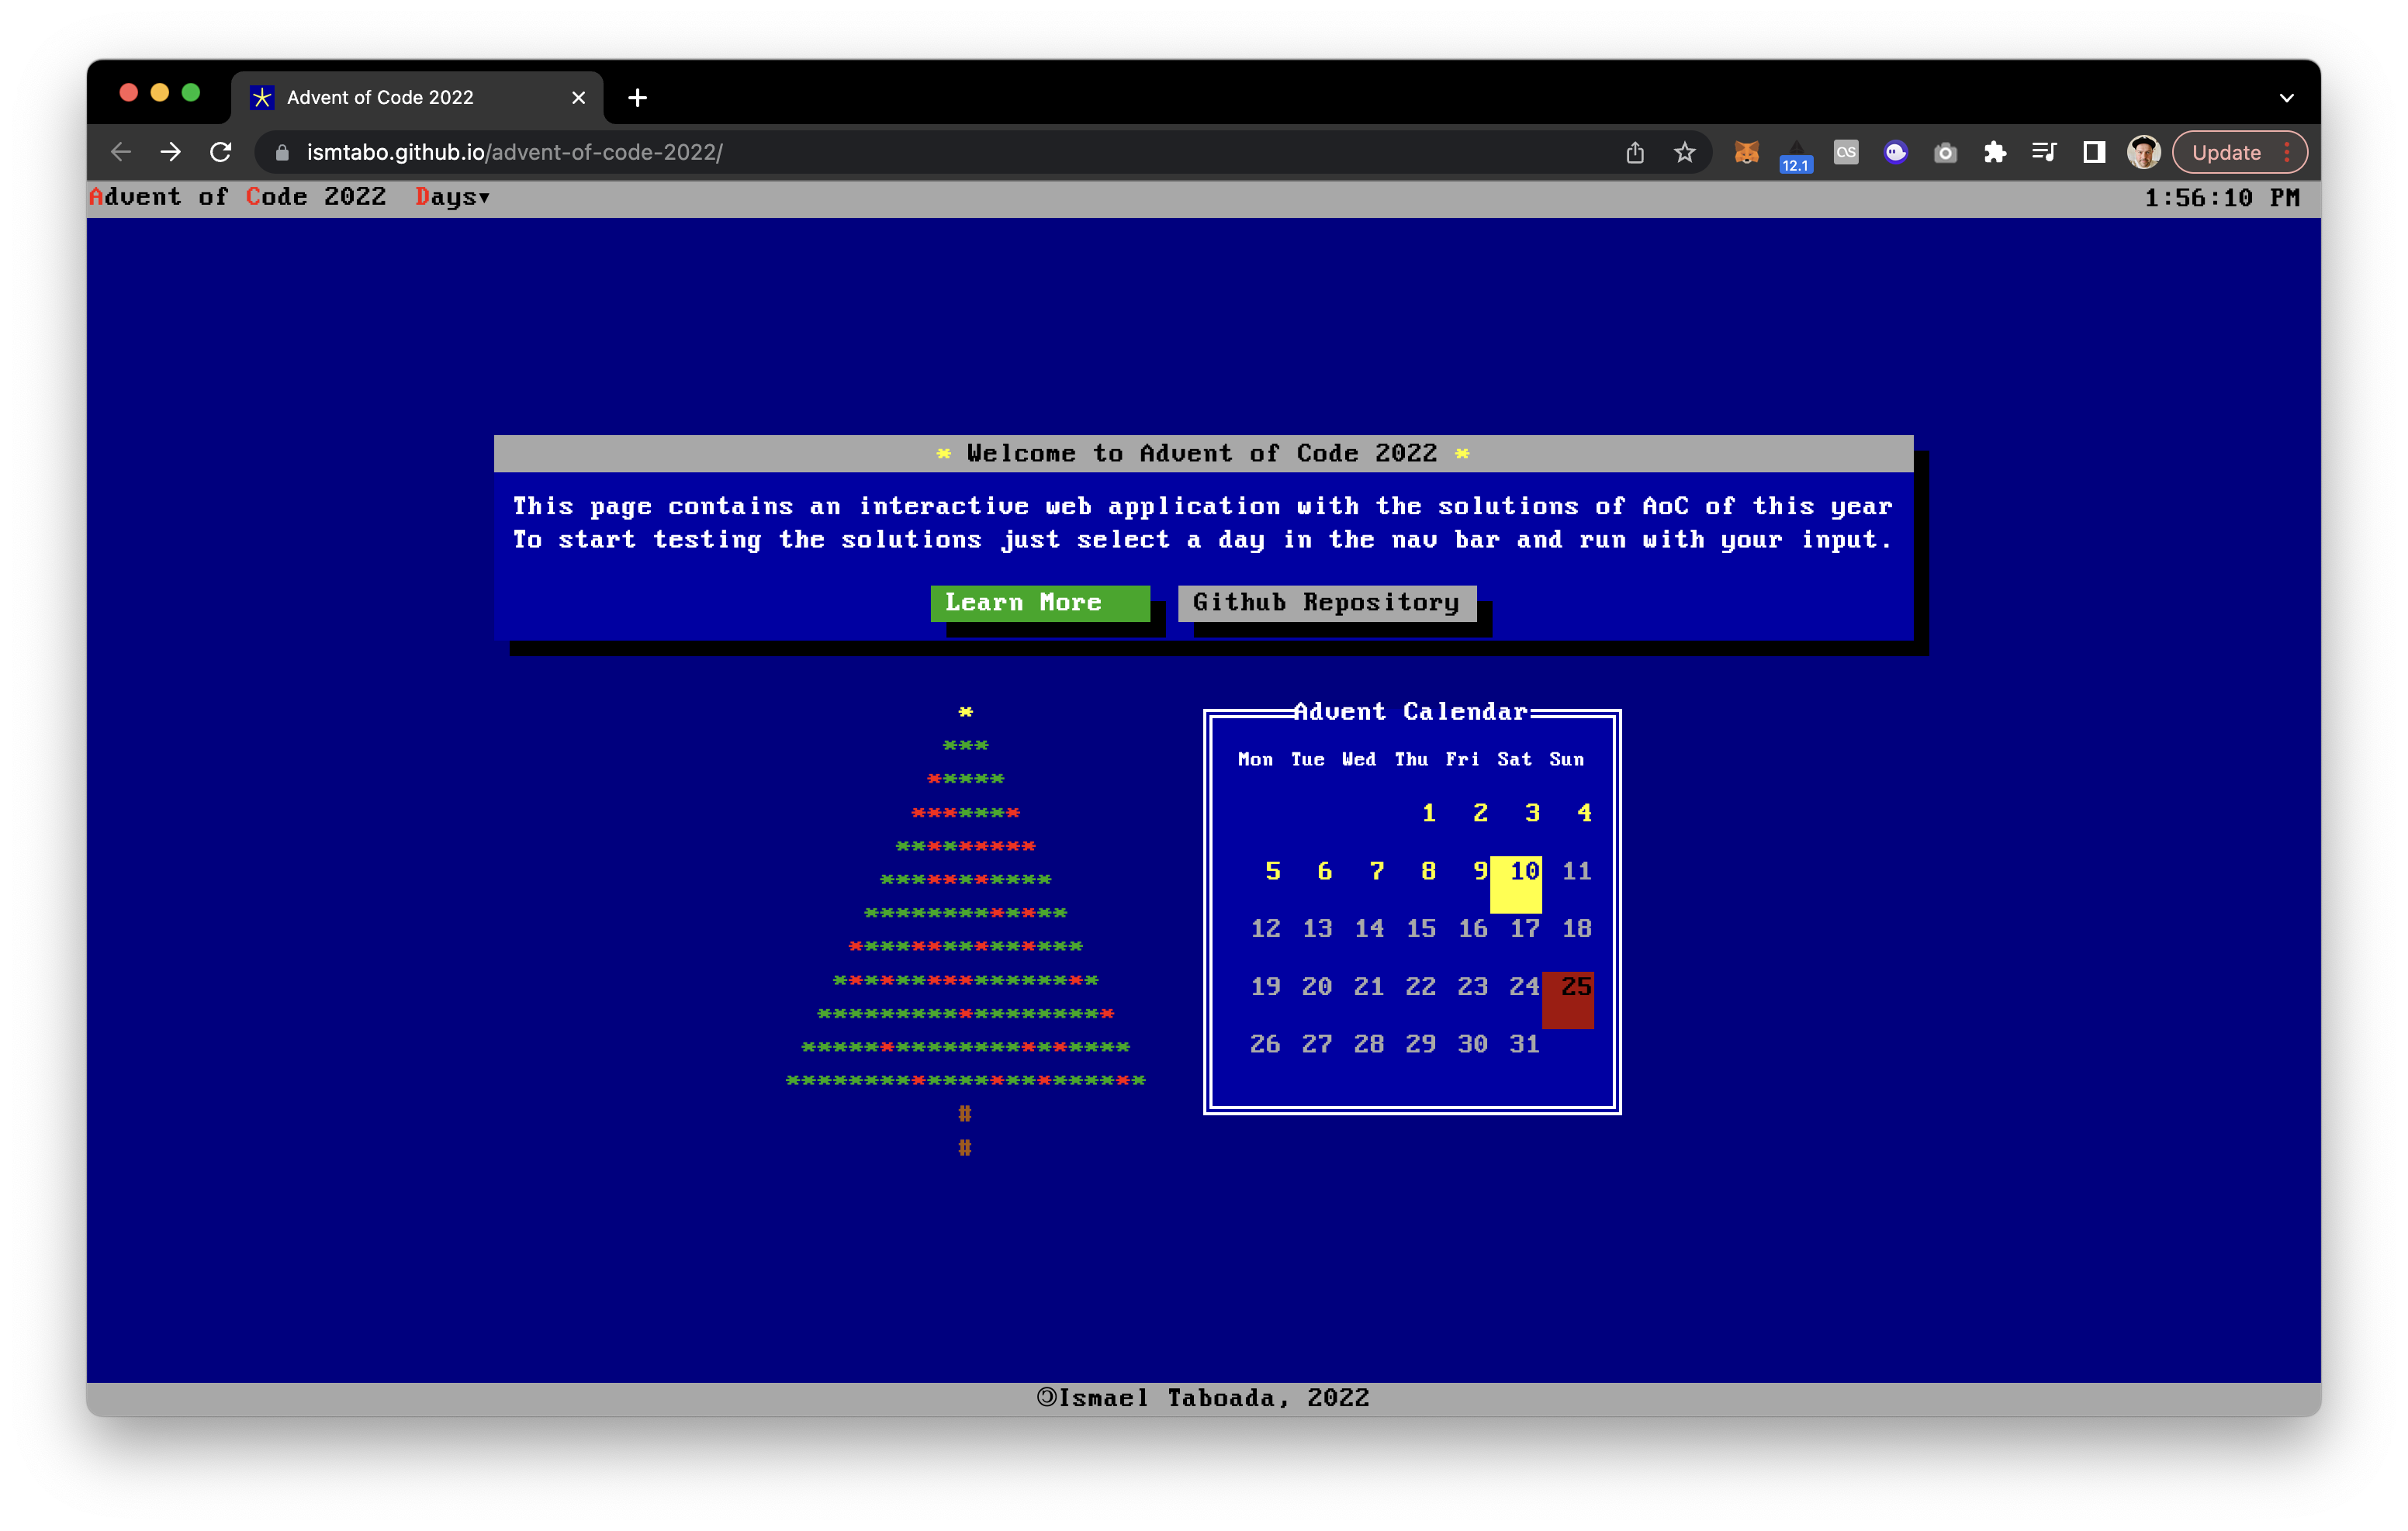
Instead of just using a single language, I wanted to solve the puzzle in a language I know, then lurk the internet for the solution in another language each day.
 Read article
It's not Thanksgiving without the stuffing...
 Read recipe
Our first foray into outdoor plants, flowers, and herbs in Chicago.
 Read article
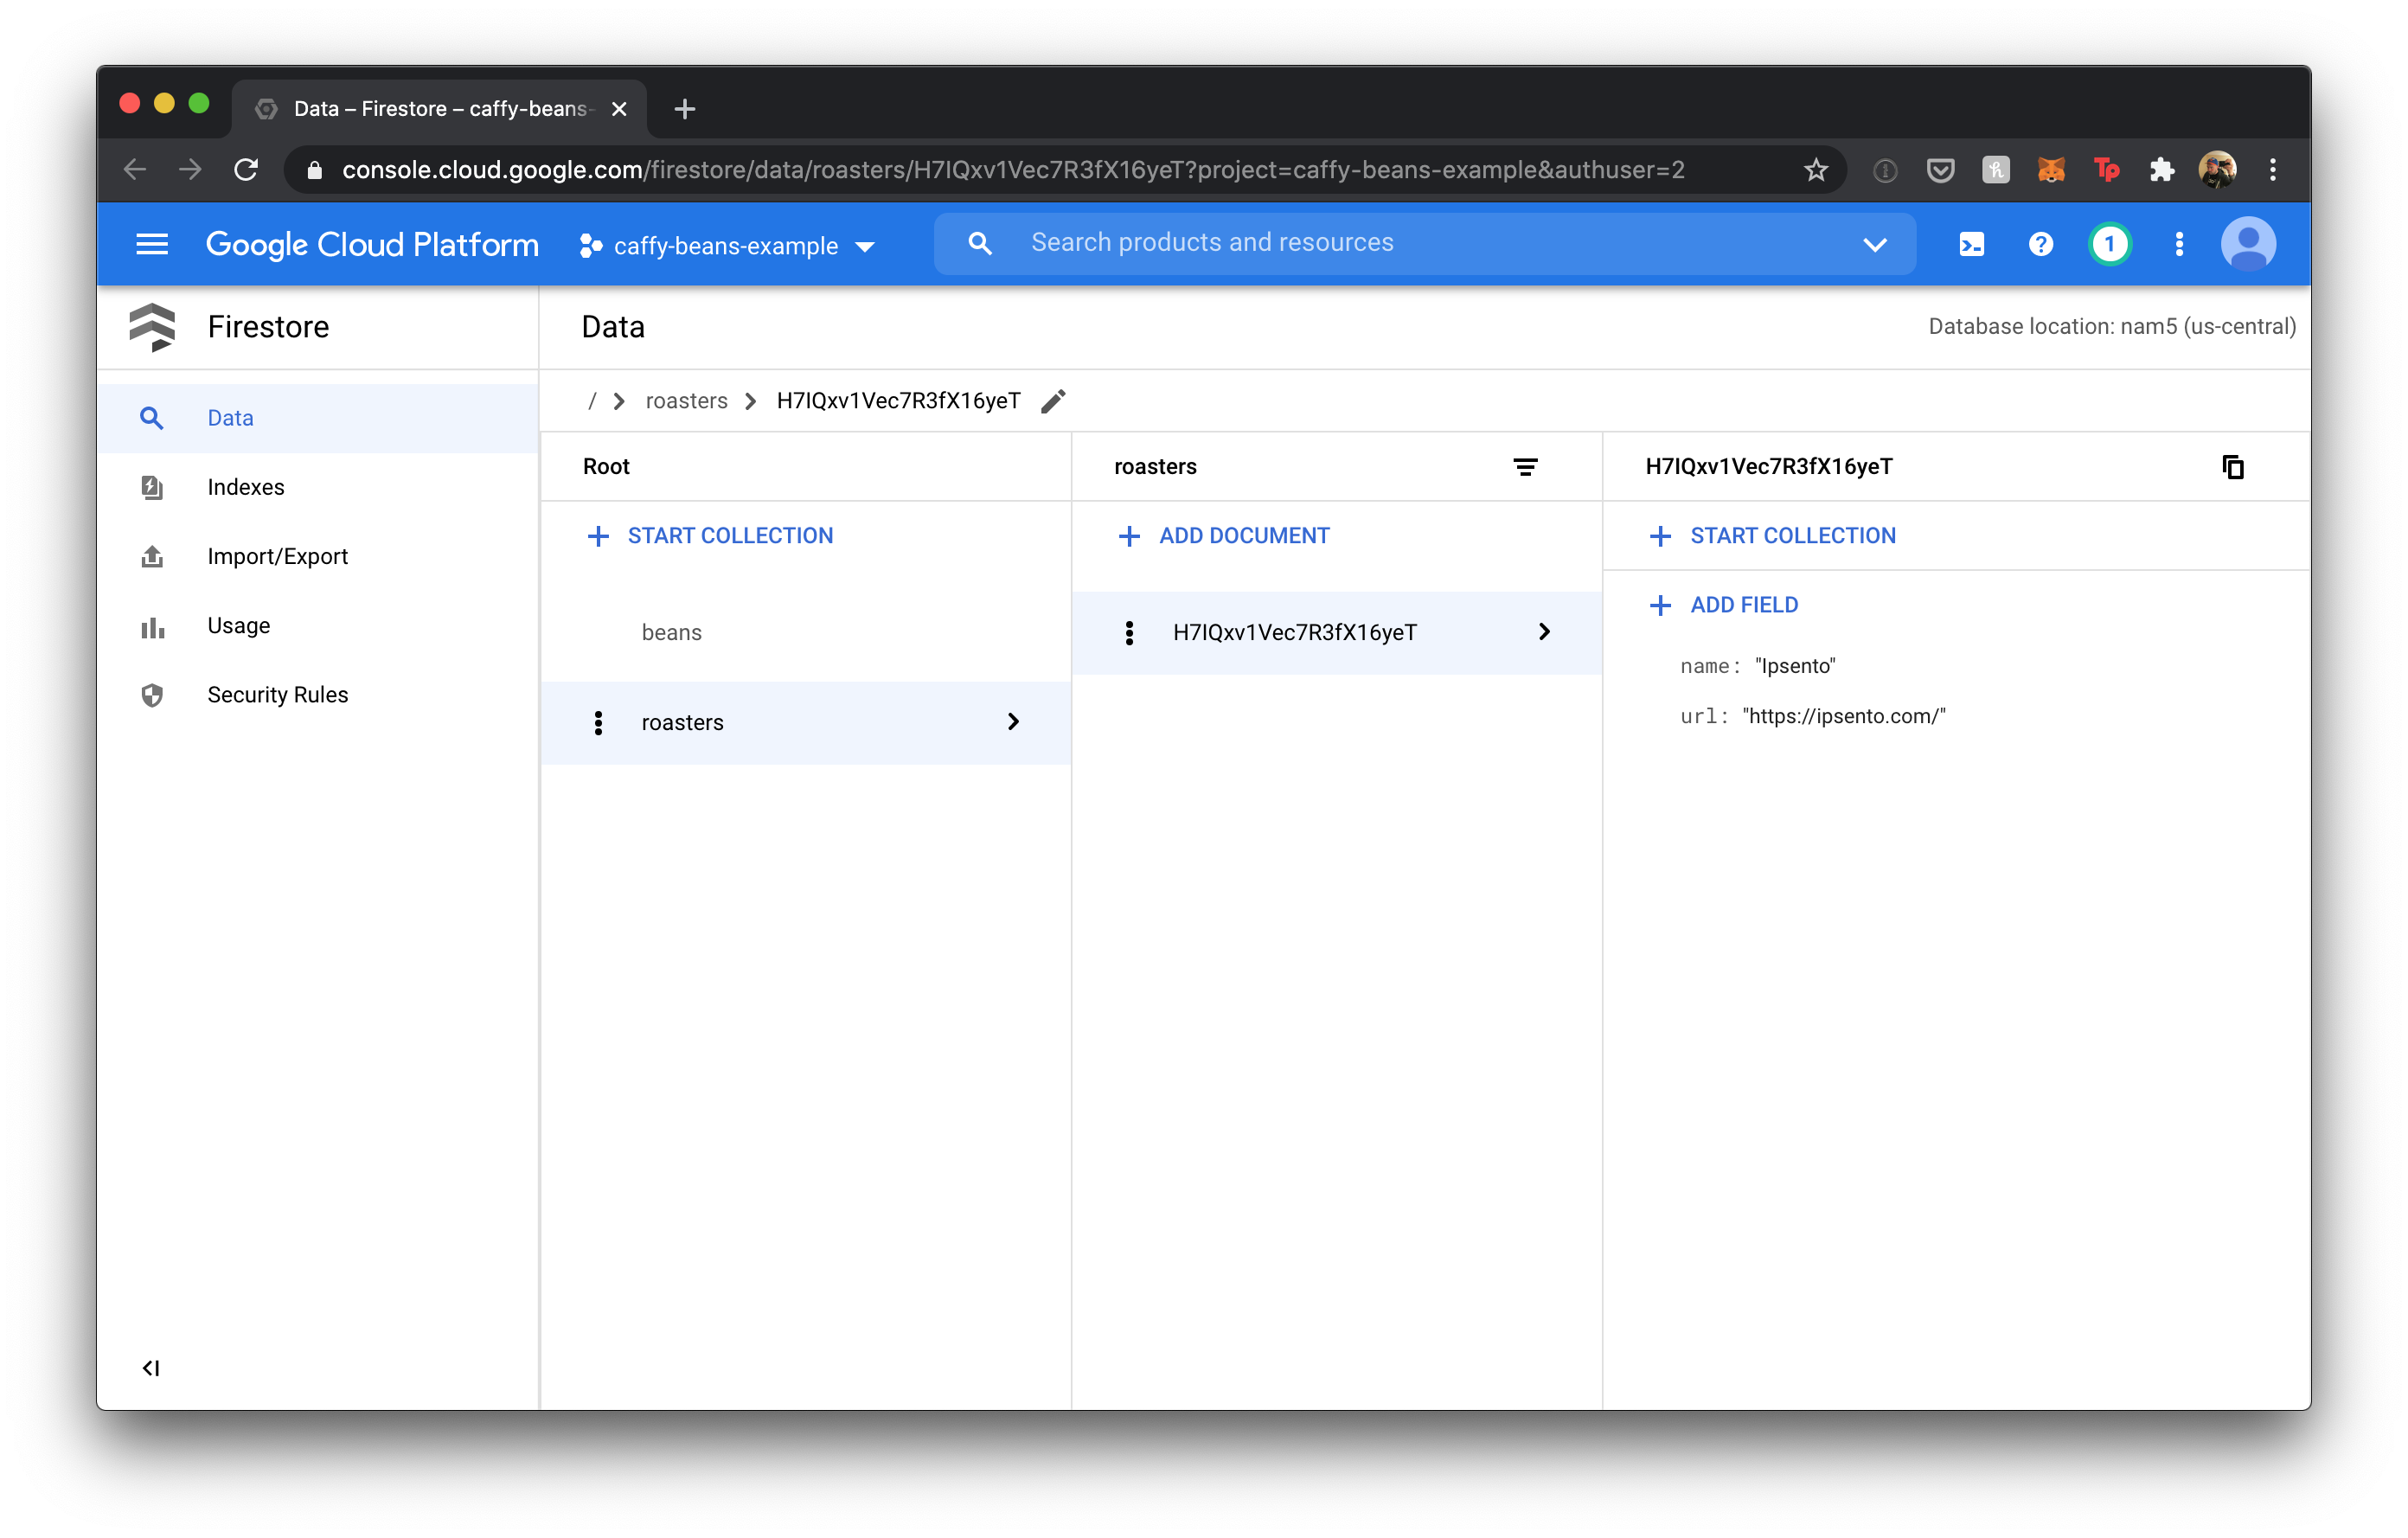
How I used Go Fx dependency injection and Firestore to build an open coffee bean database and REST API from scratch — full walkthrough from blank main.go to deployed app.
 Read article
One of my go-to "last meals" that you need to try before you die.
 Read recipe
I stole this recipe from the November 2019 Bon Appetit. This expertly spiced & glazed turkey is cut into pieces, dry-rubbed overnight, and glazed continuously during it's slow cook. It's still the best turkey I've ever had.
 Read recipe
Your new go-to cookie recipe, great for quarantining.
 Read recipe
March 2020: What I'm Doing
 Read article
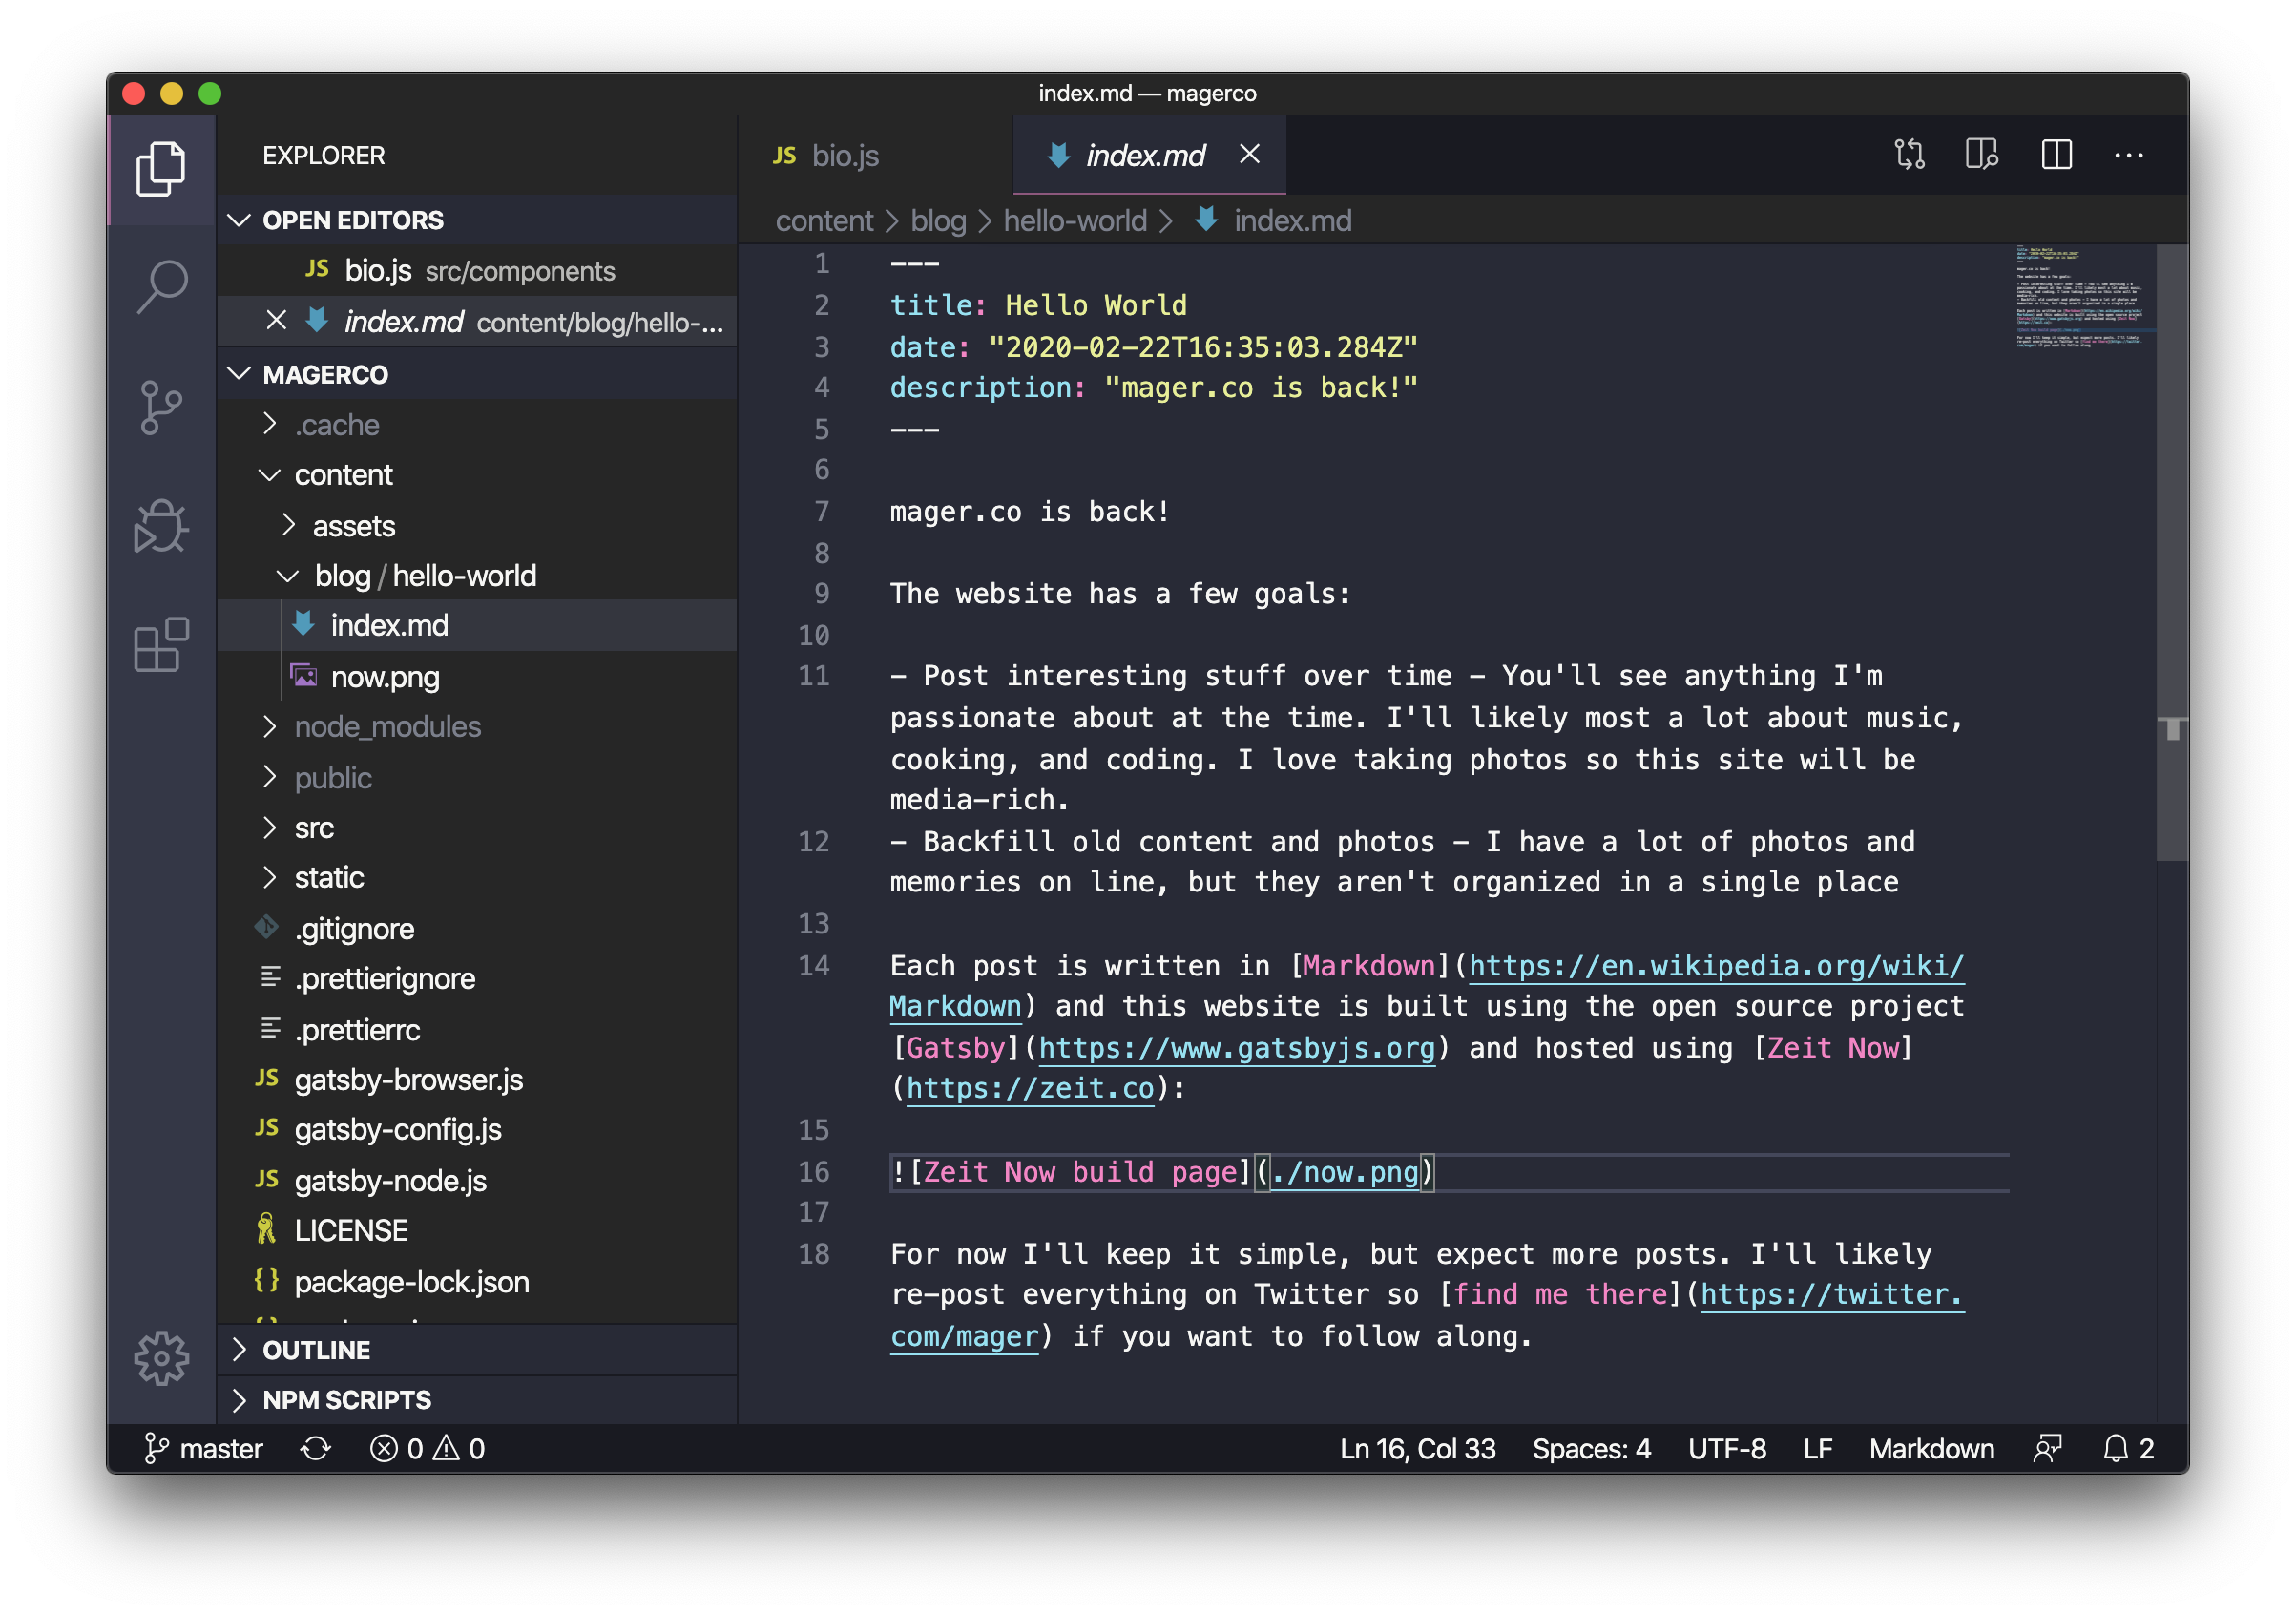
mager.co is back after years away. Here's what I'm building, what I'm obsessing over, and why this time it sticks.
 Read article
My explorations into decentralized apps and blockchain.
 Read article
Announcing my move from Ning to SimpleGeo to help build the new San Francisco office.
 Read article
Starting at Ning in Palo Alto, learning Git, and commuting via Caltrain.
 Read article
Looking back on my two years at CNET/BNET before moving on to the next chapter.
 Read article
How registering lespaul.com as a kid led to a cease and desist—and a Black Beauty guitar.
 Read article
A set of resolutions for the new year, from health and patience to cooking more and strengthening BNET.
Read article144 entries · newest first
Models write compact regression tests. Code checks the exact results. No model judge.
Preliminary calibration, not a general model ranking.
Explore the Counterexample Lab What changed in 1.1